Based on the SOA-C02 exam guideReport an error
SOA-C02· AssociateWeek 2 · Day 1~39 min read
Day 1 - The Internals of CloudWatch Metrics: Namespace, Dimension, Resolution, Cardinality
When you open the CloudWatch console, you are overwhelmed by an endless pile of graphs. EC2 CPU, ELB Request Count, Lambda Duration, RDS Connections, ECS CPU Reservation… An operator has to decide within 5 seconds, from inside this pile, "is our service dying right now?" To do that, you need to know how metrics are stored, how they are indexed, and how they are billed. If you only memorize the console UI, you won't be able to find the graph again after five minutes, and you only run into a cardinality explosion once the bill arrives.
Today we look deeply, from the operator's point of view, at CloudWatch Metrics' data model, time resolution, retention policy, cardinality traps, and cost structure. On the exam, it shows up as decision scenarios like "should we turn on detailed monitoring, or go all the way to 1-second resolution?" and "should we track per-user latency as a dimension?"
The CloudWatch Metrics Data Model
A single metric data point is identified by a tuple of the following 6 elements.
DataPoint = (Namespace, MetricName, Dimensions[], Timestamp, Value, Unit)
| Element | Example | Meaning |
|---|---|---|
| Namespace | AWS/EC2, AWS/RDS, MyApp/Production | Metric container. An AWS service or user-defined (may contain /) |
| MetricName | CPUUtilization, RequestCount | Name of what is being measured |
| Dimensions | InstanceId=i-abc, Env=Prod | key=value pairs that identify the metric (up to 30 per metric) |
| Timestamp | 2025-05-26T14:30:00Z | Measurement time (millisecond precision) |
| Value | 75.0 | A single value or a statistic set ({Sum, Min, Max, SampleCount}) |
| Unit | Percent, Milliseconds, Bytes | Unit. CloudWatch supports some unit conversion |
Key fact: (Namespace, MetricName, the exact set of Dimensions) is treated as the unique metric. In other words, even with the single name CPUUtilization, if you have 100 EC2 instances there are 100 separate metrics (the InstanceId dimension values differ). To see the average across 100 instances, you have to aggregate separately with the Math Expression AVG(METRICS()) or the console's "Add math" feature.
CloudWatch is known to be built internally on a time-series DB similar to OpenTSDB or Druid. Metrics are indexed by (namespace, metric_name, normalized hash of the dimension_set) for fast lookup. However, if dimension combinations explode, the same metric_name creates hundreds of thousands of different metrics, and cost and query latency explode. This is called cardinality explosion, and Prometheus, InfluxDB, and Datadog all have the same trap. CloudWatch charges $0.30 per metric per month (for the first 10,000), so adding one wrong dimension makes the bill jump into four digits immediately.
⚠️ Trap: "Let's put
user_idin a dimension to track per-user latency" is a common anti-pattern. With 1 million users, 1 million metrics are created, and one month costs $300,000(!). Per-user analysis should go not into metrics but into logs (Logs Insights), OpenSearch, or EMF's metadata fields (ordinary log fields that are not metric dimensions). When you see the keywords "per-user / per-request analysis" on the exam, a Custom Metric dimension is almost always the wrong answer.
Time Resolution: Standard vs High-Resolution
A CloudWatch metric is stored at one of two resolutions.
| Resolution | Data point interval | Minimum alarm evaluation period | Cost | When to use |
|---|---|---|---|---|
| Standard (60 seconds) | 1 minute | Evaluation every 10 seconds is possible, but data is in 1-minute units | Standard | Most workloads |
| High-Resolution (1 second) | 1 second | 10-second or 30-second alarms possible | Standard + alarm 1.5x ($0.30/metric is the same) | Fast auto scaling, 30-second to 1-minute spikes |
AWS standard metrics are at 60-second resolution by default (for EC2, you must turn on detailed monitoring to get 1 minute, otherwise 5 minutes). For user metrics, enable 1-second resolution with StorageResolution=1 when calling PutMetricData.
# Publish a 1-second resolution metric — StorageResolution=1
aws cloudwatch put-metric-data \
  --namespace "MyApp/Realtime" \
  --metric-data \
    "MetricName=ActiveSessions,Value=4823,Unit=Count,StorageResolution=1"
As a hypothetical case, a game company runs a workload where a traffic spike every minute lasts only 30 seconds. With standard 60-second metrics, the 30-second spike was buried in the 1-minute average, so the ASG reacted late (the threshold-breach signal appeared only when half of the spike was already over). After switching to a 1-second resolution metric + Step Scaling, spike detection time dropped from 60 seconds to 10 seconds. The cost is $0.30 per metric per month (high resolution does not make the per-metric price higher, though alarm cost is 1.5x), but the 5xx losses from lacking instances were far larger, so the ROI was justified immediately.
The retention period of High-Resolution metrics is the same (15 months), but they are automatically aggregated (rolled up) to lower resolutions over time. 1-second resolution is kept for only 3 hours, then aggregated to 60-second resolution, then to 5 minutes after 15 days, and to 1 hour after 63 days, shrinking step by step. Therefore 1-second resolution data from a year ago cannot be queried. If you need long-term retention, export with GetMetricData or stream it with a CloudWatch Metric Stream to Kinesis Firehose → S3.
Metric Retention Policy: A Four-Step Staircase of Automatic Downsampling
[Resolution]   1 sec   →   60 sec   →   5 min   →   1 hour   →  (deleted)
[Retention]    3 hours      15 days      63 days      15 months
               ───────────────────────────────────────────►
Facts an operator must memorize:
- After 3 hours, 1-second data disappears (aggregated to 60 seconds)
- After 15 days, 1-minute data disappears (aggregated to 5 minutes)
- After 63 days, 5-minute data disappears (aggregated to 1 hour)
- After 15 months (455 days), data is permanently deleted
If you need long-term retention, use CloudWatch Metric Stream → Kinesis Firehose → S3 (GA in 2021), or periodically export with the GetMetricData API. If you write SLO/SLI reports quarterly or yearly, you have to bury the data in S3.
This is an implementation of roll-up / down-sampling, the standard pattern of time-series DBs. Prometheus's recording rules + remote write to Thanos, Graphite's storage-aggregation, InfluxDB's continuous query, and RRDtool's RRA (Round Robin Archive) are all the same concept. The reason the amount of data shrinks automatically over time reflects the operational fact of "precise for recent data, macro-level for old data." Because the standard SLO analysis window is 28–30 days, this policy alone is often sufficient.
EC2 Detailed Monitoring vs Basic Monitoring
EC2 provides Basic Monitoring at 5-minute intervals for free. Detailed Monitoring (per-minute metrics) costs about $2.10 per instance per month (7 metrics × $0.30).
| Metric | Basic (5 min) | Detailed (1 min) | CloudWatch Agent (guest OS) |
|---|---|---|---|
| CPUUtilization | ✅ | ✅ | (duplicate) |
| NetworkIn/Out, NetworkPacketsIn/Out | ✅ | ✅ | - |
| DiskReadOps/WriteOps, DiskReadBytes/WriteBytes | ✅ | ✅ | - |
| EBSReadOps/WriteOps (Nitro) | ✅ | ✅ | - |
| StatusCheckFailed, StatusCheckFailed_System/Instance | ✅ | ✅ | - |
| MemoryUtilization (mem_used_percent) | ❌ | ❌ | ✅ |
| DiskSpaceUtilization (disk_used_percent) | ❌ | ❌ | ✅ |
| SwapUtilization | ❌ | ❌ | ✅ |
| TCPv4 EstablishedConn, NetStat | ❌ | ❌ | ✅ |
⚠️ Trap: Memory and disk utilization do not appear even if you turn on EC2 detailed monitoring. These must be measured inside the guest OS, so the CloudWatch Agent is required. When an "EC2 memory utilization alarm" or "alarm before the disk fills up" scenario appears on the exam, the answer is almost always the CloudWatch Agent. Another trap that shows up: "Auto Scaling cannot scale out based on memory" → you have to apply the ASG's target tracking to the custom metric published by the Agent.
EC2 measures CPU, network, and disk I/O at the hypervisor level (currently the Nitro System). That is why it can be collected regardless of the guest OS and is visible even if the guest hangs. But memory needs page table and cache statistics inside the OS, so the hypervisor cannot see it. For the same reason, disk "usage" (file system level, df -h) is also invisible — EBS read/write IOPS (block device level) are visible. This trade-off is an inherent limit of IaaS, and for services like ECS Fargate and Lambda, where AWS operates even the guest OS, memory is included in the standard metrics.
Key CloudWatch Agent Installation Commands
# Install the Agent via SSM (operator standard)
aws ssm send-command \
  --document-name "AWS-ConfigureAWSPackage" \
  --parameters action=Install,name=AmazonCloudWatchAgent \
  --targets "Key=tag:Env,Values=Prod"

# Store the Agent config in Parameter Store, then retrieve it
aws ssm put-parameter \
  --name "/cloudwatch-agent/prod/config" \
  --value file://amazon-cloudwatch-agent.json \
  --type String

# Start the Agent
aws ssm send-command \
  --document-name "AmazonCloudWatch-ManageAgent" \
  --parameters action=configure,mode=ec2,\
optionalConfigurationSource=ssm,\
optionalConfigurationLocation=/cloudwatch-agent/prod/config,\
optionalRestart=yes \
  --targets "Key=tag:Env,Values=Prod"
This pattern is the answer to the exam's "deploy memory metrics to hundreds of EC2 instances in bulk" scenario. The combination of SSM Run Command + Parameter Store.
Custom Metrics: The Cost Trap of PutMetricData
To have an application publish metrics directly, use the PutMetricData API. Patterns operators often run into:
# Publish a metric via the CLI — a single data point
aws cloudwatch put-metric-data \
  --namespace "MyApp/Production" \
  --metric-name "OrderProcessingLatency" \
  --value 234 \
  --unit Milliseconds \
  --dimensions "Service=Checkout,Env=Prod" \
  --storage-resolution 60

# Publish as aggregated statistics (StatisticValues) — reduces API call cost
aws cloudwatch put-metric-data \
  --namespace "MyApp/Production" \
  --metric-name "OrderProcessingLatency" \
  --statistic-values \
    "Sum=12450,Minimum=120,Maximum=890,SampleCount=53" \
  --unit Milliseconds \
  --dimensions "Service=Checkout,Env=Prod"
Cost structure:
- PutMetricData API calls: $0.01 per 1,000 requests ($0.00001 per call)
- Metric storage: $0.30 per metric per month (first 10,000), with decreasing unit price beyond that
- GetMetricData: $0.01 per 1,000 metric-seconds
As a hypothetical case, a company called PutMetricData on every HTTP request to record response time (3 metrics × an average of 100M calls/day). When they saw the bill a month later, the CloudWatch Metrics API cost alone was $8,000. Fix: embed metrics in logs with Embedded Metric Format (EMF) → CloudWatch extracts them automatically (EMF has zero API calls). The cost dropped 95%. The depth of EMF is covered in Week 2 Day 4.
PutMetricData accepts at most 1,000 data points + a 1MB payload per call. When an operator publishes metrics directly, always batch them to minimize the number of calls. It is common for API call cost to be much larger than metric storage cost. Also, if you publish only the per-minute aggregated result with StatisticValues (one Sum/Min/Max/SampleCount set instead of N individual data points), the number of calls drops to one sixtieth. However, percentiles can only be calculated when raw values exist, so if you want to see p99, you must publish raw.
Statistic vs ExtendedStatistic: The Lie of the Average
Multiple statistics can be extracted from the same metric.
| Statistic | Meaning | When an operator uses it |
|---|---|---|
| Sum | Total | Total requests, total errors, cumulative transfer |
| Average | Mean | CPU/memory average (beware it hides the long tail) |
| Minimum/Maximum | Min/Max | Extreme-value alarms, "even one instance hits 100%" |
| SampleCount | Number of data points | Detecting missing data |
| p50, p90, p95, p99, p99.9 | Percentiles (Extended Statistic) | The long tail of the latency distribution |
| TM(percent) | Trimmed Mean | A mean with both extremes cut off. Removes the effect of outliers |
| WM, PR, TC, TS | Wins Mean, Percentile Rank, Trimmed Count, Trimmed Sum | Sophisticated statistics |
The judgment "Lambda's average response time is 200ms, so it's stable" is dangerous. If 1% of requests take 5 seconds, p99 is 5,000ms — 1% of users have a very bad experience. Operators look at p95 and p99, not the average. On the exam, a "monitor the long tail of user experience" scenario almost always has a percentile statistic as the answer. A company that defines its SLO by the average effectively has no SLO.
The long tail of latency is the result of a "Power Law" distribution. The 80/20 rule that Pareto discovered in the 19th century also applies to latency distributions. Gil Tene's talk "How NOT to Measure Latency" (Strange Loop 2015) is required viewing for operators — it explains why the average lies, together with the trap called Coordinated Omission. AWS's latency SLOs are also defined as "p99 < N ms," and the average is rarely used in SLOs.
Math Expressions: Combining and Deriving Metrics
You can combine multiple metrics in one graph or alarm with CloudWatch's Math Expression.
m1 = ALBRequestCount (Sum, 1 min)
m2 = ALBTargetResponseTime (Average, 1 min)
m3 = ALBHTTPCode_Target_5XX_Count (Sum, 1 min)

e1 = m1 * m2                    # Total response time (summed latency)
e2 = m1 / 60                    # Requests per second (RPS)
e3 = (m3 / m1) * 100            # 5xx error rate (%)
e4 = ANOMALY_DETECTION_BAND(e3, 2)  # ML-based dynamic baseline
Commonly used patterns:
- Error rate =
(5xxCount / RequestCount) * 100 - RPS =
RequestCount / 60 - Average across multiple instances =
AVG(METRICS()) - Sum across multiple instances =
SUM(METRICS()) - Anomaly band =
ANOMALY_DETECTION_BAND(m1, 2)(standard deviation ±2) - fill =
FILL(m1, 0)(fill gaps with no data with 0) - rate of change =
RATE(m1)(rate of change per unit time, turning a cumulative counter into RPS)
Math Expressions can also be used as the direct input of an alarm. A rule such as "alarm only when the 5xx error rate exceeds 5%" cannot be expressed with a single metric (numerator and denominator are different metrics). You calculate the ratio with a Math Expression and set the threshold on that resulting expression. In the alarm's Metrics field, you list expressions like [m1, m2, e1], and the one expression with ReturnData=true becomes the alarm's input. You add it from the console's "Add math" menu, and the expression's ID becomes the alarm identifier.
Anomaly Detection: ML-Based Dynamic Baselines
Fixed-threshold alarms (e.g., CPU > 80%) produce an explosion of false positives for workloads whose traffic pattern differs by time of day. Anomaly Detection learns a metric's daily, weekly, and hourly patterns and generates a dynamic baseline.
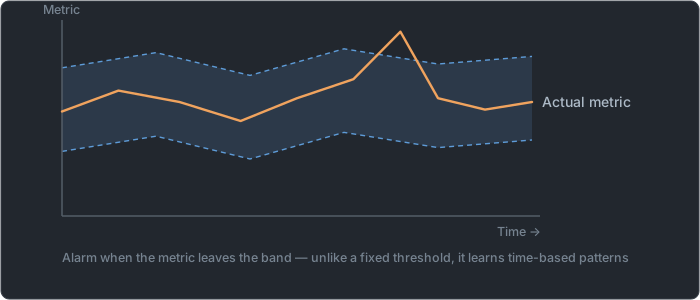
CloudWatch learns from the most recent 2 weeks (14 days) of data to build a regression model in the STL/ARIMA family. Model training takes 5 to 15 minutes, and it retrains every hour to adapt to pattern changes. The operator only needs to specify the standard deviation multiplier (usually 2 or 3).
This is a cloud implementation of STL (Seasonal-Trend decomposition using LOESS) (Cleveland et al., 1990, Journal of Official Statistics) or ARIMA (AutoRegressive Integrated Moving Average) models. It is in the same family as OSS such as Facebook Prophet (Taylor & Letham, 2017), Twitter AnomalyDetection (2015), Netflix Surus, and LinkedIn Luminol. ML replaces the burden of manually tuning thresholds for each time of day.
As a hypothetical case, an e-commerce company had traffic peaks at 12 noon and 7 PM every day, and weekends had a different pattern from weekdays. When they made alarms with fixed thresholds, dozens of false positives every day led to early-morning pages. After adopting Anomaly Detection, no alarms fired within the usual patterns (lunch and dinner peaks, weekend pattern), and only unexpected sudden traffic changes (Black Friday, outages, bot attacks) were detected accurately. Operator night pages dropped by 80%.
Anomaly Detection should be applied after at least 2 days of data, and for stability 2 weeks of data, have accumulated. If applied immediately to a new metric, almost every data point is flagged as an anomaly due to insufficient training data. On the exam, the answer to the "we applied anomaly detection immediately to a new service and false alarms are exploding" scenario is "enable after data accumulates."
CloudWatch Metric Stream: Near-Real-Time External Export
Metric Stream, GA in 2021, streams metric changes to Kinesis Firehose in near real time (< 2 minutes). Patterns operators often run into:
[CloudWatch Metric Stream]
    │ (OpenTelemetry 0.7 or JSON)
    ▼
[Kinesis Data Firehose]
    │
    ├─→ S3 (long-term retention / Athena analysis)
    ├─→ Datadog (external monitoring integration)
    ├─→ New Relic / Splunk
    └─→ Lambda (custom processing)
Advantages:
- More cost-efficient than polling GetMetricData every minute
- Near-real-time delivery (push-based)
- Supports the OpenTelemetry standard format
If you poll every metric every minute with GetMetricData, API call cost and latency explode. Metric Stream pushes CloudWatch's internal metric publish events directly to Firehose, so the polling pattern disappears. It is the standard way for operators to move metrics to external tools such as Datadog and New Relic. The cost is $0.003 per 1,000 metric updates + standard Firehose charges.
Summary
The operator's checklist for CloudWatch Metrics:
- Manage dimension cardinality: do not put high-cardinality fields such as user_id and request_id in dimensions (use EMF's metadata instead)
- Use High-Resolution only when truly needed: limited to workloads with 30-second to 1-minute spikes
- EC2 memory and disk require the CloudWatch Agent: deploy in bulk with SSM Run Command
- For user metrics, prefer EMF over PutMetricData: zero API cost
- Alarm on p95/p99, not the average: protect against the long tail
- Use Anomaly Detection for metrics with large fluctuation patterns: but only after training data accumulates
- For long-term retention, use Metric Stream → Firehose → S3: bypasses the 15-month automatic deletion
Tomorrow is CloudWatch Logs, the partner of metrics. We look deeply at log groups, streams, retention policies, Subscription Filters, and the VPC Flow Logs cost trap.
📝 Practice Questions
Click a choice to reveal the answer and explanation.
Question 1
You want to create an EC2 memory utilization alarm. How do you collect it?
Question 2
To detect fast traffic spikes, you want the ASG to react in 10-second units instead of 1 minute. Which option is needed?
Question 3
A Lambda function's average response time is 200ms, but some users report a very slow experience. Which metric and statistic should the operator look at?
Question 4
An operator wants to monitor the ALB's 5xx error rate (error count / total requests). How do you build it?
Question 5
An operator called PutMetricData on every HTTP request and the API cost exploded. What is the most efficient alternative?
Question 6
After how many hours is CloudWatch metric 1-second resolution data aggregated to 60-second resolution?
Question 7
To create an alarm without false positives for a workload that has lunch and dinner traffic peaks every day and a weekend pattern different from weekdays?
Question 8
A company used UserId as a metric Dimension to track the latency of 1 million users individually. What caused the bill to explode, and what is the fix?