Based on the SAA-C03 exam guideReport an error
SAA-C03· AssociateWeek 1 · Day 5~60 min read
Day 5 - Week 1 Review: Fundamentals and IAM, Hardened Through Scenarios
Over one week we covered everything from global infrastructure to multi-account governance. Even if you feel like you know it all in your head, the SAA-C03 exam always asks by twisting it into a one-line scenario. From the single sentence "data can't leave headquarters," Outposts should come to mind, and from "minimize global latency for a TCP game server," Global Accelerator should pop out immediately. The exam isn't trying to filter out people who didn't memorize keywords; it's trying to select people who can quickly judge "what is the essence of this scenario."
This article is the time to review Week 1 and etch the scenario keyword → solution mapping into your head. It isn't simple memorization; we'll re-examine "why that's the answer" once more. Scenario mapping is also an area where reading it through once more the day before the exam clearly raises your odds of passing. And in practice, this mapping becomes the "ability to review a design someone else built before an incident happens" — every incident we saw in Week 1 (Capital One, us-east-1, the Tokyo AZ, SolarWinds, Travis CI) ultimately happened when someone confused the same mapping.
Redrawing the Week 1 Picture
[ AWS Global Infrastructure ]
       │
       ├── Region (34) ──┬── AZ (3+) ──┬── DC
       │                 │             └── DC
       │                 └── AZ ── DC
       ├── Edge Location (600+) ── CloudFront / R53 / GA / WAF
       ├── Local Zone (30+) ── mini Region
       ├── Wavelength ── 5G edge
       └── Outposts ── customer DC

[ Identity ]
   User / Group / Role / Policy
       │
   AssumeRole (STS) → temporary credentials
       │
   ┌─── External ID (Confused Deputy defense)
   ├─── Permissions Boundary (permission ceiling)
   ├─── ABAC (tag-based)
   └─── OIDC/SAML (federation)

[ Multi-Account ]
   Organizations → OU tree
       │
   ┌─── SCP (account permission ceiling)
   ├─── Control Tower (automated Landing Zone)
   ├─── RAM (resource sharing)
   └─── StackSets (bulk deployment)
These three areas are the conclusion of Week 1, and it's accurate to say that every service from Week 2 to Week 12 sits on top of these three planes. Networking operates on top of AZs, security on top of IAM, and multi-account patterns on top of Organizations. And the intersection of these three planes — "who can do what to a resource in which Region and which AZ of which account" — ultimately becomes the coordinate system for every SAA scenario.
This 3-layer model is actually a mapping of the classic 3 axes of distributed-system security — Where (location), Who (identity), What (resource) — onto cloud operations. In addition to the three security elements NIST defined in 1985 (Confidentiality / Integrity / Availability), the three areas codified by NIST SP 800-53 in 2003 — Access Control (AC), Audit & Accountability (AU), and System and Communications Protection (SC) — match almost one-to-one. AC is implemented by IAM, AU by CloudTrail/Config, and SC by VPC/network controls.
These 3 layers are also reflected as-is in AWS's actual permission evaluation engine. AWS Zelkova (formal verification of IAM) and Tiros (formal verification of networks) convert IAM/SCP policies and VPC routing into SMT constraints respectively to solve "is this request reachable." The 2018 USENIX Security paper "Semantic-based Automated Reasoning for AWS Access Policies" is the basis of Zelkova, and "Reachability Analysis for AWS-based Networks," presented the same year, is the basis of Tiros. Access Analyzer, Reachability Analyzer, and IAM Access Advisor all run on top of this.
Scenario Keyword Mapping
| Scenario keyword | Candidate answer | Reason |
|---|---|---|
| "Keep data inside HQ" + "use AWS APIs" | Outposts | AWS hardware inside the customer DC |
| "5G", "autonomous driving", "AR/VR" | Wavelength | Carrier edge |
| "Post-production VFX", "users in LA/Miami" | Local Zones | City-level mini Region |
| "TCP/UDP", "gaming", "VoIP" | Global Accelerator | L4 acceleration |
| "HTTP static content caching" | CloudFront | L7 caching |
| "DNS failover" | Route 53 | DNS routing |
| "Multi-account", "Okta SSO" | IAM Identity Center | SAML/SCIM federation |
| "Deploy to AWS from GitHub Actions" | OIDC federation | Short-lived tokens |
| "External SaaS monitoring" | Cross-Account Role + External ID | Confused Deputy defense |
| "Developers create Roles but broad permissions are forbidden" | Permissions Boundary | Permission ceiling |
| "Block a specific Region in all accounts" | SCP | Account permission ceiling |
| "Automatically apply a baseline to new accounts" | Control Tower + StackSets | Automated Landing Zone |
| "Share a VPC across multiple accounts" | AWS RAM | Resource sharing |
| "Safe way for EC2 to access S3" | Instance Profile + IAM Role | Prevents key exposure |
| "Enforce MFA" | Policy Condition aws:MultiFactorAuthPresent | IAM enforcement |
| "Service stays up if one AZ dies" | Multi-AZ ASG + ELB | HA pattern |
| "1-second RPO even if a Region dies" | Aurora Global Database | DR pattern |
| "Data sovereignty + Korean FSS regulation" | Outposts / domestic Region | Data location restriction |
| "Grant AWS permissions while keeping the existing IdP" | IAM Identity Center + SAML | External IdP federation |
| "Lambda accesses another account's S3" | Cross-Account Role + Resource Policy | Allow needed on both sides |
| "AWS permissions for Active Directory users" | AD Trust + IAM Identity Center | Enterprise standard |
| "Time-limited permissions for temporary staff" | Session Tag + Permissions Boundary | Automatic expiry + ceiling |
| "Block unintended public exposure of S3 buckets" | Block Public Access (account + bucket, 4 settings) | Data leak prevention |
This table can be read through in 30 minutes the day before the exam, and if you review the same mapping 5 or more times, candidate answers will come to mind from just the first line of a scenario in the exam room. The keyword → solution mapping best shows the "pattern-recognition exam" nature of SAA.
⚠️ Trap: There are also many cases where the same keyword leads to different answers. Is "encryption" KMS or CloudHSM? For single-company use it's KMS; for FIPS 140-2 Level 3 regulation (FedRAMP High, some financial) it's CloudHSM. Is "DR" Multi-AZ or Cross-Region? AZ-level isolation is Multi-AZ; Region-level isolation is Cross-Region. Don't look only at keywords; look together at "what is the threat model of this scenario."
CAP/PACELC and Mapping AWS Services
SAA doesn't ask about this directly, but it's decisive for interpreting scenarios. If you don't know the trade-offs of distributed systems, you can't answer questions like "why can't this option give strong consistency." And this mapping is also used directly in practice when debugging "why did our service's global consistency break."
| Service | Consistency model | Position |
|---|---|---|
| DynamoDB (default) | Eventually Consistent | AP |
| DynamoDB (strong) | Strong Consistent (single Region) | CP |
| DynamoDB Global Table | Multi-Master, Last-Writer-Wins | AP |
| Aurora (single region) | Strong | CP |
| Aurora Global DB | Async replication | AP (across Regions) |
| RDS Multi-AZ | Sync replication | CP |
| S3 | Strong read-after-write (since 2020.12) | CP |
| EFS | Strong (close-to-open) | CP |
| ElastiCache for Redis (Cluster Mode) | Async replication | AP |
| FSx for Lustre | Strong (POSIX) | CP |
| Neptune | Strong (single writer) | CP |
DynamoDB's strong consistency is offered as an option only within a single Region (ConsistentRead=true), and Global Tables are always eventual. Global Table conflict resolution is based on Last-Writer-Wins (LWW), so data can be lost on concurrent writes. So if you need multi-master global writes, use a DynamoDB Global Table, but first weigh whether "timestamp conflicts are acceptable for the business." If you need stricter consistency, you need CRDTs (Conflict-free Replicated Data Types) or consensus algorithms based on Paxos/Raft, and AWS partly provides this through Aurora's quorum-based replication (6-way write across 3 AZs, with 4/6 read and 3/6 write quorums). The Aurora paper Amazon Aurora: Design Considerations for High Throughput Cloud-Native Relational Databases (SIGMOD 2017) is the essence of this architecture.
Case: In 2015, GitHub had its data consistency broken for 24 hours by a partition incident in its own MySQL cluster. A network partition occurred between two data centers, and each side judged itself to be the primary and accepted writes, a split-brain incident. In the post-incident report, GitHub stated explicitly, "when partitioned, we choose CP and give up availability." Cases like this show that CAP's trade-off isn't abstract theory but a decision operators face every day. AWS made the same decision in RDS Multi-AZ, which is why availability drops for about 60 seconds during failover.
⚠️ Trap: It's wrong to assume that "Aurora is strongly consistent, so the global DB is too." Aurora Global Database uses storage-level async replication (typically 1-second RPO) and the secondary Region is read-only. If you want global writes, you have to use a DynamoDB Global Table, but then you must accept the conflict risk of LWW. Also, viewing it as "ElastiCache Redis Cluster Mode is async replication but guarantees availability via multi-AZ failover" is partially wrong too — writes that haven't been acked can be lost during failover.
Reviewing the Shared Responsibility Model
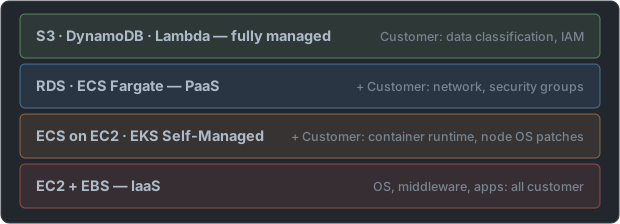
The higher the service abstraction, the higher the responsibility boundary moves. Even so, data classification, IAM, and encryption key management are always the customer's — that's the key point. This principle is shown most clearly by the Capital One incident — AWS had fulfilled its responsibility for its own infrastructure, and the incident came from a WAF misconfiguration (SSRF), IMDSv1, and excessive IAM permissions in the customer's area.
Case: In June 2022, a Toyota subsidiary had an incident in which an access key was exposed in a public GitHub repository for 5 years. About 300,000 customers' data was put at risk, and the cause was a developer pushing credentials along with the code. AWS's responsibility was 0% — everything happened in the customer's area of responsibility. The standard post-incident recommendations are ① IAM Role + IRSA/Instance Profile instead of IAM User, ② if you must issue an Access Key, temporary credentials from IAM Identity Center, and ③ blocking commits with a Git pre-commit hook (git-secrets, truffleHog). The same pattern of incident repeated at Uber (2016), Imperva (2019), and Codecov (2021).
The shared responsibility model differs subtly from service to service. For RDS, DB engine patching (minor versions) is AWS's, while major version upgrades are the customer's choice. For Lambda, runtime patching is AWS's, while migration after a runtime EOL is the customer's (Node 14 → 18, etc.). For ECS Fargate, the container OS and runtime are AWS's, while patching OS packages inside the image is the customer's. These subtle differences are used as exam traps. AWS Trusted Advisor and AWS Security Hub's Foundational Security Best Practices (FSBP) automatically check these responsibility boundaries.
Policy Evaluation Decision Tree
Request → SCP(Org) → Resource Policy → Identity Policy → Permissions Boundary → Session Policy
   Explicit Deny at any stage → DENY immediately
   Pass all stages → ALLOW
   No Allow anywhere → DENY (default)
Same account = union, cross-account = intersection, KMS = Key Policy must explicitly delegate. These three lines are the whole of IAM evaluation logic. If you're asked in an interview to "explain AWS IAM evaluation logic in 1 minute," these three lines are the answer.
Trap: An answer choice saying "if only the Resource Policy allows, Cross-Account works" is wrong. That's true for the same account, but cross-account also requires an Allow in the caller account's Identity Policy. Also, KMS is a special case — unless the Key Policy explicitly delegates to IAM (the "Enable IAM User Permissions" statement), you can't use the KMS key even if an IAM policy grants Allow. This is because KMS follows the model that "the key owner is the final authority."
Policy evaluation is actually decided by the intersection of 6 policy types — SCP, Resource Policy, Identity Policy, Permissions Boundary, Session Policy, and VPC Endpoint Policy. The "Policy Evaluation Logic" flowchart in the official AWS docs is the most accurate reference. Whether an "Allow is required vs optional" for each policy type differs by scenario. One-line summary: an explicit Deny is always final, and an Allow must pass every boundary.
This model is a mix of the security theory's Mandatory Access Control (MAC) and Discretionary Access Control (DAC). SCPs and Permissions Boundaries are MAC (limits enforced by a higher authority), and Identity/Resource Policies are DAC (set freely by the owner). It's similar to the multilevel security concept of the US military security standard Bell-LaPadula Model (1973). AWS solving policy evaluation with an SMT solver is also because this model has a structure that can be formally verified.
Standard Multi-Account Topology
| Account | Role |
|---|---|
| Management | Org management, billing. No workloads |
| Log Archive | Central storage for CloudTrail/Config. WORM |
| Audit/Security | Delegated administrator for GuardDuty, Security Hub |
| Networking | Central VPC + Transit Gateway, RAM sharing |
| Shared Services | Common tools (CI/CD, Artifactory, etc.) |
| Prod | Production workloads |
| Staging | Pre-production verification |
| Dev | Development workloads |
| Sandbox | Personal experiments. Cost and Region strictly limited via SCP |
This topology is specified as a recommended form in the AWS Security Reference Architecture (SRA) documentation. It's accurate to say that every large enterprise customer uses a variation of this. If you look at the public presentations from Netflix, Capital One, Airbnb, Slack, and others, almost the same pattern repeats.
Case: In 2019, the Netflix Tech Blog revealed its multi-account strategy, saying that while operating more than 1,000 AWS accounts it had standardized an "Account per Workload" pattern that splits accounts finely by workload, team, and environment. The reasons are ① limiting blast radius, ② cost and tag automation, and ③ simplifying IAM permissions. Spotify, Lyft, and Stripe adopted the same pattern, and this is the real-world model of the topology that SRA recommends. As of 2023, large companies typically operate 100 to 5,000 accounts, and the AWS Organizations limit (10,000 accounts per Org) is effectively the ceiling.
The practical core of multi-account operations is two automations. ① Account provisioning automation — with Control Tower's Account Factory or Account Factory for Terraform (AFT), creating a new account → applying the baseline → granting permissions → notification are tied into a GitOps flow. ② Automatic baseline deployment — with the SERVICE_MANAGED + auto-deployment=Enabled option of CloudFormation StackSets, a security baseline (GuardDuty, Config Rules, IAM Password Policy, S3 BPA, etc.) is automatically applied to new accounts. Without these two automations, operating 100 accounts is impossible for humans.
Key Comparisons That Are Often Confused
| Item | A | B | Difference |
|---|---|---|---|
| Local Zones | City mini Regions such as LA/Miami | Wavelength: carrier 5G edge | LZ is the regular internet, WL is mobile 5G |
| CloudFront | L7 HTTP cache | Global Accelerator: L4 acceleration | HTTP means CF, TCP/UDP means GA |
| IAM User | Permanent credentials | IAM Identity Center: temporary SSO | Multi-account / external IdP means IC |
| ZoneName | Shuffled per account | ZoneId: identical regardless of account | Use ZoneId for multi-account sync |
| Permissions Boundary | Identity permission ceiling | SCP: account permission ceiling | Different scope of application |
| Cross-Region Read Replica | Async, manual promote | Aurora Global DB: Async + fast failover (on the order of minutes) | RPO/RTO difference |
| CloudFront Functions | Edge PoP, 1 ms limit | Lambda@Edge: Regional Edge, heavier | Location/runtime difference |
| KMS | Multi-tenant HSM | CloudHSM: dedicated HSM, FIPS 140-2 L3 | Regulatory strictness |
| STS AssumeRole | General cross-account | AssumeRoleWithWebIdentity: OIDC | External IdP federation |
| Resource Policy Allow | Same-account is enough | Cross-account: Allow needed on both sides | Evaluation logic |
Trap: ZoneName vs ZoneId doesn't often appear on the exam, but in practice it's decisive in security/cost scenarios asking about "using the same AZ as another account." CloudFront vs Global Accelerator is a pair frequently compared on the exam, and if you see the keywords "TCP/UDP," "gaming," "VoIP," "MQTT," or "WebRTC signaling," it's always GA. CloudFront Functions vs Lambda@Edge is along the same comparison axis: "sub-millisecond-scale response" means Functions, and "full Node.js/Python runtime" means Lambda@Edge.
When AWS offers the same functionality through several services, the trade-off axis is always different. KMS vs CloudHSM is abstraction vs isolation, ALB vs NLB is L7 features vs L4 throughput, and SQS vs SNS vs EventBridge is point-to-point vs fanout vs schema-routing. On the SAA exam you must always identify "along which axis the trade-off is being asked." Once you master this way of thinking, you can map even an unfamiliar new service onto the same axes and narrow down candidate answers.
Wrap-Up
Week 1 was the time to etch "the coordinate system of the AWS universe" into your head. The isolation model of Region/AZ/Edge, IAM's policy evaluation, and multi-account governance. These three become the backdrop for every topic in the remaining 11 weeks. Next week we'll layer networking (VPC, subnets, routing) on top of them. Don't try to understand it all at once; if you build the habit of reopening this table each time you solve a scenario question and doing the mapping, the keyword → solution mapping will be set as an automatic reflex right before the exam. And that automatic reflex is not only about passing SAA but also the core competency of a senior engineer in real-world design who "can sketch 3 candidate solutions within a 30-minute meeting."
📝 Practice Questions
Click a choice to reveal the answer and explanation.
Question 1
A global gaming company wants to provide consistent TCP-based game server response times to users around the world. What is the most suitable solution?
Question 2
A financial company must keep some data inside its headquarters under Korean Financial Supervisory Service regulations while still operating through AWS APIs. What is the most suitable solution?
Question 3
A company wants to block use of all Regions other than us-east-1 across 50 AWS accounts. What is the most efficient method?
Question 4
What is the safest way for EC2 to access S3?
Question 5
How do you remove the burden of key rotation when GitHub Actions deploys to AWS?
Question 6
A SaaS collects CloudWatch logs from our AWS. What is needed for Confused Deputy defense?
Question 7
A company issues 10 new AWS accounts every week and wants to apply the same security baseline to each. What is the most suitable method?
Question 8
A company wants to give new developers permission to create IAM Roles freely but prevent them from creating AdministratorAccess-level Roles. What is the most appropriate method?
Question 9
EC2 goes down due to a cooling failure in one AZ. If the ASG is already configured as multi-AZ?
Question 10
Which of the following is NOT AWS's responsibility?
Question 11
A system requires an RPO under 1 ms per transaction and operates only within a single Region. For RDS?
Question 12
A company wants to share the VPC subnets of a central Networking account with 30 other workload accounts within Organizations. What is the most suitable solution?