Based on the SAA-C03 exam guideReport an error
SAA-C03· AssociateWeek 1 · Day 1~37 min read
Day 1 - The Map of AWS Infrastructure: Regions, AZs, and the Promise Called Shared Responsibility
The first time you open the AWS console, there's a Region selector like "Seoul" in the top right corner. Some services say "Global," while others only work once you pick a Region. If you've ever been stuck on what separates the two, that is exactly the first question a Solutions Architect has to answer.
In this article we'll draw the physical map of how AWS's global infrastructure is stacked up, and then sort out where "AWS's responsibility" and "my responsibility" split on top of it. The goal is not to memorize keywords for the exam, but to truly understand why our service survived (or didn't) when us-east-1 went down at 3 a.m. Once that understanding builds up, the exam questions follow naturally.
A Region Is Not Just an "Area" — It's a Cluster of Data Centers
If you understand an AWS Region only as "the name of a city with data centers," you've seen only half of it. Each Region is an isolated infrastructure unit made up of 3 or more Availability Zones (AZs), and each AZ in turn consists of one or more physical data centers (DCs). In other words, ap-northeast-2 (Seoul) is not a single building but a network of dozens of data centers spread across 4 AZs.
Why was it designed this way? When S3 launched in 2006, AWS started with just one Region (Northern Virginia, later named us-east-1). Back then even the concept of a "Region" was vague, and an AZ was just a different rack inside the same facility. Then on April 21, 2011, an EBS network failure in us-east-1 took Reddit, Quora, and Foursquare down for days. That incident forced the concept of "physical isolation" on AWS, and every Region since has been built on the principle that it has at least 3 AZs with independent power, cooling, and networking.
| Component | Count (as of 2025) | Design meaning |
|---|---|---|
| Region | 34 | The unit that decides data sovereignty / pricing / service availability |
| Availability Zone (AZ) | 3 or more per Region | Physical isolation. The minimum unit of HA design |
| Edge Location | 600+ | CloudFront / Route 53 / Global Accelerator |
| Local Zones | 30+ | Ultra-low latency within 1-2 ms (gaming, media, ML inference) |
| Wavelength Zone | Carrier 5G edge | For mobile 5G devices |
| Outposts | Customer data center | On-premises regulation / hybrid |
Case: On February 28, 2017, at 9:37 a.m. (Pacific time), an operator debugging the billing system in S3 us-east-1 made a typo in a command and took down far more servers at once than intended. As a result the index subsystem went into a full restart, and for 4 hours Stripe, Slack, Trello, IFTTT, Coursera, Quora, and others were down. The AWS Status Page itself depended on S3, so you even had the situation of "there's an outage right now, but the status page shows green." It showed how depending on a single Region can shake half the internet. AWS official post-event summary.
What an Availability Zone Means: The Boundary Between Isolation and Synchronous Replication
If you understand an AZ simply as "one data center," you'll get exam questions wrong and cause big incidents in practice. An AZ is a set of one or more physically independent DCs, and even DCs within the same AZ use separate power and cooling. AZs are linked by dedicated low-latency fiber with an average of 60 μs to 2 ms, close enough for synchronous replication, yet far enough apart that a fire or power outage in one AZ doesn't spread to another (typically a few km to tens of km).
🔍 Going deeper: The fact that latency between AZs is typically 1-2 ms is the core constraint behind RDS Multi-AZ design. RDS Multi-AZ does synchronous physical replication between the Primary and the Standby. That is, for the client to receive a commit, the Primary waits until it gets a write ack from the Standby. If the RTT between AZs is 1-2 ms, the extra latency per transaction stays at about that much, but if you tried synchronous replication across Regions (e.g., Seoul ↔ Tokyo, RTT about 35 ms), OLTP workloads would become practically impossible. That is why cross-Region replication defaults to asynchronous (e.g., Aurora Global Database, RDS Cross-Region Read Replica).
                    [ AWS Global Infrastructure ]
                              |
        +---------------------+---------------------+
        |                     |                     |
   [Region: ap-northeast-2 (Seoul)]            [Region: us-east-1]
        |
   +----+----+----+----+
   |    |    |    |
  AZ-a AZ-b AZ-c AZ-d
   |    |    |    |
  DCs  DCs  DCs  DCs  ← each AZ has 1 or more physical DCs
                       ← each DC has independent power and network
   Synchronous replication possible (1-2ms RTT)
Comparing it with other clouds' isolation models makes AWS's design philosophy easier to see.
| Dimension | AWS | GCP | Azure |
|---|---|---|---|
| Geographic location | Region | Region | Geography |
| Isolation unit | Availability Zone (3+ per Region) | Zone (usually 3 per Region) | Availability Zone (3 guaranteed only in some Regions) |
| Wide-area group | (none) | (none) | Region Pair (automatic pairing) |
| AZ naming | Mapped per account (ap-northeast-2a ≠ the neighboring account's ap-northeast-2a) | Same for all accounts (us-central1-a) | Numeric mapping in some Regions (1, 2, 3) |
| Single-DC API | (limited) Outposts, Local Zones | (none) | Availability Set (rack-level isolation) |
The reason AWS maps AZs to different physical AZs per account is traffic distribution. If every customer said "let's create in zone a first," the load would pile onto a alone, so AWS deliberately shuffles it per account. So to place resources in the same AZ across two accounts, you have to compare ZoneId (e.g., apne2-az1), not ZoneName.
⚠️ Trap: An answer choice saying "an AZ is one data center" shows up on the exam. It's wrong. An AZ is a logical isolation unit that groups one or more DCs. Another trap is ZoneName vs ZoneId. When designing VPC peering or PrivateLink between companies, matching on AZ name alone often attaches you to a different physical AZ in practice, making cost and latency spike.
Case: On August 23, 2019, in one AZ of the AWS Tokyo Region (ap-northeast-1), a bug in the cooling system's control software caused some servers to overheat, affecting EC2 and EBS. The lessons were twofold. First, a Single-AZ deployment takes RDS and EBS down with it (because storage is tied to one AZ). Second, spreading an Auto Scaling Group across AZs is your insurance. Workloads configured as multi-AZ in an ASG survived, while the ones tied to a single AZ all went down.
Edge Locations: Beyond Content Caching
Edge locations are not just CDN cache points. AWS uses more than 600 edge PoPs (Points of Presence) to do 4 different things.
- CloudFront: Caches static and dynamic HTTP/HTTPS content. TLS termination happens here too.
- Route 53: Handles global DNS authoritative responses at the edge.
- Global Accelerator: Pulls TCP/UDP traffic into the nearest edge and delivers it over the AWS backbone network. Provides 2 Anycast IPs.
- AWS WAF / Shield: Filters DDoS and malicious traffic at the edge.
CloudFront and Global Accelerator are often confused, but they operate at fundamentally different layers. CloudFront is OSI L7 (understands HTTP semantics and caches), while Global Accelerator is OSI L4 (accelerates the TCP/UDP packets themselves). So whenever you see non-HTTP traffic such as game servers, MQTT, VoIP, or WebRTC signaling, it is almost always Global Accelerator.
CloudFront Functions and Lambda@Edge both run at the edge, but in different places. CloudFront Functions run directly on the 600+ edge PoPs and respond with a cold start under 100 μs, but have limits of 2 MB memory and 1 ms execution time. Lambda@Edge runs on the 13 Regional Edge Caches and can use the full Node.js and Python runtimes, but cold starts are in the tens of ms. The difference between the two shows the trade-off of "how heavy a logic can you run at the edge."
The static Anycast IPs that Global Accelerator provides are based on BGP Anycast. When the same IP is advertised from multiple edges, the client's ISP routes to the nearest edge according to BGP's best-path algorithm (AS_PATH length, local preference, etc.). Thanks to this structure, traffic can be rerouted within seconds without waiting for DNS TTLs. This contrasts with Route 53-based failover, which takes minutes because of DNS cache TTLs.
Special Infrastructure: What Outposts, Local Zones, and Wavelength Are For
You can tell these three apart quickly by keywords on the exam, but if you understand why they exist, you'll never confuse them.
Outposts is a service that brings an AWS hardware rack straight into the customer's data center. Why is it needed? Under Article 14 of the Electronic Financial Supervision Regulation, Korean financial institutions must keep some data in their own domestic facilities, and in Europe the GDPR Schrems II ruling (EU Court, 2020) put restrictions on using US clouds. In such regulatory environments you want "data inside our building" while still "operating through AWS APIs." The answer is Outposts.
Local Zones are mini Regions connected to the same backbone as the large Regions but placed geographically close to major cities. They're in cities like Los Angeles, Miami, and Las Vegas, and provide only basic services such as EC2, EBS, and ECS. They were built for workloads like film post-production (VFX), cloud game streaming, and AR/VR, where users notice immediately when latency exceeds 10 ms.
Wavelength consists of edge data centers inside carriers' (Verizon, KDDI, Vodafone, SK Telecom, etc.) 5G networks. Since traffic reaches compute resources directly from the base station without passing through the 5G core network, it's used for applications that "interact directly with the physical world," such as autonomous-vehicle perception processing and industrial IoT.
Memory tip: Inside HQ = O(utposts), city = L(ocal Zones), 5G = W(avelength). On the exam, though, you need to look at the scenario's "latency requirement" and "data location constraint" together, not just the keywords.
The Shared Responsibility Model: A Contract Between AWS and the Customer
A common misconception among first-time cloud users is "doesn't AWS take care of security too?" In reality there is a clear division: AWS = Security OF the Cloud / Customer = Security IN the Cloud. It's nearly accurate to say that everything from the concrete floor up to the hypervisor is AWS, and everything above that is the customer's responsibility.
Let's start with why this model is needed. In traditional on-premises, everything was the customer's responsibility (servers, network, OS, apps, all of it). In SaaS, almost everything is the vendor's responsibility (if Gmail goes down, it's Google's fault). The cloud is in between, and the responsibility boundary shifts depending on which service you use. With EC2 (IaaS), the customer owns everything from the OS up; with RDS (PaaS), AWS handles up to DB engine patching; with fully managed services like Lambda or S3, AWS takes responsibility even further up.
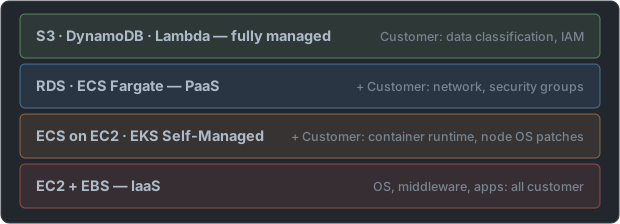
| Responsibility area | AWS | Customer |
|---|---|---|
| Physical facilities / hardware | ✅ | - |
| Hypervisor / host OS | ✅ | - |
| Guest OS patching (EC2) | - | ✅ |
| Managed service OS / engine patching (RDS/Lambda) | ✅ | - |
| Network traffic protection (SG / NACL) | - | ✅ |
| Data classification / encryption key policy | - | ✅ |
| IAM users / permissions / policies | - | ✅ |
| Inter-AZ traffic encryption (infrastructure) | ✅ | - |
| Application code vulnerabilities | - | ✅ |
Case: In July 2019, an incident occurred in which the credit card application data of 106 million people was leaked from Capital One. The perpetrator was Paige Thompson, a former AWS employee, but the cause was not AWS itself; it was an SSRF vulnerability in the WAF that Capital One operated plus exposure of an IAM role through the EC2 instance metadata service (IMDSv1). The attacker used SSRF to access http://169.254.169.254/latest/meta-data/iam/security-credentials/, stole temporary credentials, and used them to read S3 buckets. AWS had fulfilled its responsibility for its own infrastructure, but the incident happened in "the customer's area of responsibility" (WAF configuration, the permission scope of the IAM role, use of IMDSv1). DOJ indictment PDF. As a direct result of this incident, AWS released IMDSv2 (session-token based) in November 2019.
IMDSv2 works in two steps. ① Send a PUT /latest/api/token request with the X-aws-ec2-metadata-token-ttl-seconds header to get a session token. ② Present the token in the X-aws-ec2-metadata-token header when requesting metadata. An SSRF attacker can usually only send HTTP GET, so they can't send a PUT and can't get a token, which means metadata access is blocked. At the same time, IMDSv2 requests force the IP TTL to 1 (a hop limit of 1), so the metadata is reachable only from inside the instance and cannot escape outside the container network.
Well-Architected Framework: Not Just a Checklist
AWS has organized good cloud design into 6 Pillars. It started from an internal best-practice document in 2012, was made public in 2015, and became 6 when Sustainability was added in 2021.
- Operational Excellence — IaC, automation, change management, observability
- Security — Least privilege, security at every layer, data protection, incident response
- Reliability — Self-healing, Multi-AZ, distribution, backup and DR
- Performance Efficiency — Right-sizing, going global, serverless, data patterns
- Cost Optimization — Appropriate pricing models, removing unused resources, measurable costs
- Sustainability — Minimizing carbon footprint, Region selection, efficient workloads
This nearly matches the SAA exam's domain weights (Design Resilient Architectures 26%, High-Performing 24%, Security 30%, Cost Optimization 20%). So in scenario questions, if you first pin down "which Pillar is this scenario asking about" rather than "which answer is right," the answer becomes visible. For example, a scenario about "an analytics job used only at night" is asking about Cost Optimization, and the answer is on the Spot or Scheduled Scaling side. If "the service must stay up even if one AZ dies," it's asking about Reliability, and the answer is the Multi-AZ, ASG, and ELB combination.
Memory tip: Just take the initials: O-S-R-P-C-S. More important than memorizing, though, is practicing the mapping "scenario keyword → Pillar → solution pattern."
Typing It Out with the CLI — The Fastest Way to Make It Stick
If you only memorize it in words, you'll forget. Typing it by hand in the CLI even once makes a difference.
# 1) List all available Regions
aws ec2 describe-regions --output table

# 2) AZ info for the Seoul Region — look at ZoneName and ZoneId together
aws ec2 describe-availability-zones \
  --region ap-northeast-2 \
  --query 'AvailabilityZones[*].[ZoneName,ZoneId,State,ZoneType]' \
  --output table
The output looks like this.
+-------------------+-----------+-----------+-----------------------+
| ap-northeast-2a   | apne2-az1 | available | availability-zone     |
| ap-northeast-2b   | apne2-az2 | available | availability-zone     |
| ap-northeast-2c   | apne2-az3 | available | availability-zone     |
| ap-northeast-2d   | apne2-az4 | available | availability-zone     |
+-------------------+-----------+-----------+-----------------------+
ZoneName is shuffled per account, but ZoneId is the same in every account. So if you're peering a VPC with a partner company and want to "place them in the same AZ to save cross-AZ costs," you have to match by ZoneId. Also, if ZoneType comes out as local-zone or wavelength-zone, it means that Region supports that special infrastructure.
Wrap-Up
We saw two pictures today. First, AWS operates on a 3-tier infrastructure of Region > AZ > Edge, and each tier has different levels of isolation and latency characteristics. Second, on top of that infrastructure, the responsibility for security and operations is split by the promise that AWS owns everything from the concrete floor to the hypervisor, and the customer owns what's above. When you use managed services, the boundary moves up and customer responsibility shrinks accordingly, but "data classification and IAM permissions" never shrink.
These two pictures form the backdrop for every area of the SAA exam. In the next article we'll look, on top of this infrastructure map, at the 4 core IAM entities that decide "who gets to do what" — User, Group, Role, and Policy. If you remember that the excessive permissions on the IAM role credentials stolen via SSRF made the damage worse in the Capital One incident, it will be natural to see why this topic matters.
📝 Practice Questions
Click a choice to reveal the answer and explanation.
Question 1
A company must run some workloads inside its headquarters data center but also wants to use AWS managed services. What is the most suitable solution?
Question 2
Which of the following is AWS's responsibility when operating an EC2 instance?
Question 3
What provides the most consistent global latency for a TCP/UDP-based global game server?
Question 4
Which of the following about S3 is correct?
Question 5
Which of the following is NOT a pillar of the Well-Architected Framework?
Question 6
A company runs RDS Multi-AZ in the ap-northeast-2 Region and wants to place a read replica in a separate Region (ap-northeast-1). What is the main benefit of this design?