Based on the MLS-C01 exam guideReport an error
MLS-C01· AssociateWeek 1 · Day 2~24 min read
Day 2 - Data Storage for ML: S3, EFS, FSx for Lustre, and Data Formats
📌 Key Takeaways
- The most common reason GPUs sit idle is not that the model is slow but that the data does not arrive on time.
- There are three input modes: File (copy everything, then start) / Pipe (streaming, starts immediately) / FastFile (streaming + POSIX random access).
- In distributed training,
ShardedByS3Keymakes each instance read only a different piece, whileFullyReplicatedreplicates everything. - The key branch is repeated, high-throughput = FSx for Lustre; shared, general-purpose = EFS; one-off large sequential = S3 Pipe.
- For formats: structured analytics and ETL = Parquet (columnar), large sequential training with built-in algorithms = RecordIO-protobuf. Millions of small files are merged by sharding.
S3: The Center of the ML Data Lake
The GPUs on an ml.p4d instance consume several GB per second, and if storage cannot match that speed, the expensive accelerators idle while waiting on I/O. That is why the Specialty exam asks "which data goes where, in which format" as a cost-and-performance trade-off.
Nearly all SageMaker training data starts in S3. It offers virtually unlimited capacity with 11 nines of durability, and SageMaker reads it natively. The key is choosing the input mode, which is how to stream data from S3 to the GPU.
| Input mode | Behavior | Suitable situation | Cost |
|---|---|---|---|
| File mode | Copies all data to instance disk (EBS) before training | Small data, random access needed, simplicity first | Startup delay; EBS capacity ≥ data size |
| Pipe mode | Streams from S3, not stored on disk | Large data, sequential access, minimizing startup delay | Random access and full shuffle are hard; format restrictions |
| FastFile mode | Accesses only the files needed on demand, like POSIX | Large data where only part is read, or random access | Per-file latency can accumulate |
[File mode]   ████ full copy (tens of minutes) ████ ▶ training starts ────────▶
[Pipe mode]   ▶ training starts ─── continuously fed by streaming ─────────▶
[FastFile]    ▶ training starts ─── fetches only needed files as needed ──▶
              └ time-to-first-batch: File ≫ FastFile ≈ Pipe
from sagemaker.inputs import TrainingInput

# Pipe mode: stream instead of downloading everything → fast start on large data
train_input = TrainingInput(
    s3_data="s3://my-lake/features/train/",
    input_mode="Pipe",                 # File | Pipe | FastFile
    distribution="ShardedByS3Key",     # split data across multiple instances
    content_type="application/x-recordio-protobuf",
)
estimator.fit({"train": train_input})distribution="ShardedByS3Key": In multi-instance distributed training, each instance reads only a different piece of the data, eliminating duplication.distribution="FullyReplicated": Every instance receives the whole dataset. Suitable for small data and validation sets.
With File mode, the first step runs only after the full copy before training finishes. For hundreds of GB, this copy alone takes tens of minutes while the expensive GPUs idle. Pipe mode starts training as soon as the first batch arrives, so time-to-first-batch is short. However, Pipe is sequential streaming, so a full shuffle each epoch is hard, and the algorithm must support Pipe. FastFile is a compromise between the two: it supports random access while avoiding the full copy.
⚠️ Pitfall: The simplification "Pipe is always faster" is dangerous. If the data is small and a random shuffle each epoch matters, File/FastFile is better. In the passage you must check all three clues: data size, access pattern, and format.
EFS and FSx for Lustre: Accelerating Training I/O
S3 is object storage, so it cannot do directory operations and random reads quickly like a POSIX file system. When training repeats the same data over many epochs or must randomly access many small files, file system storage is advantageous.
| Storage | Characteristics | ML-suitable scenario | Caution |
|---|---|---|---|
| S3 | Object storage, virtually unlimited, cheap | Data lake source, one-off large streaming | POSIX random access is slow |
| EFS | Managed NFS, shared across multiple instances, elastic scaling | Mid-sized datasets shared by notebooks and multiple jobs | Lower throughput than Lustre |
| FSx for Lustre | High-performance parallel file system, S3 integration | Large-scale distributed training, repeated reads, high-throughput needs | Extra cost and setup; excessive for one-off training |
The killer feature of FSx for Lustre is S3 repository integration. With an S3 bucket as the backend, FSx acts like a high-performance cache. You keep the data in S3 (cheap and durable), but read it at Lustre's high throughput during training.
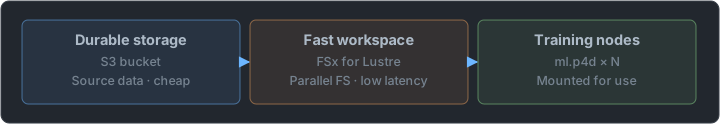
from sagemaker.inputs import FileSystemInput

# Mount FSx for Lustre directly as the training input
fsx_input = FileSystemInput(
    file_system_id="fs-0123456789abcdef0",
    file_system_type="FSxLustre",
    directory_path="/fsx/imagenet/train",
    file_system_access_mode="ro",
)
estimator.fit({"train": fsx_input})
If you repeat hyperparameter tuning (HPO) tens to hundreds of times on the same dataset, the cost of downloading from S3 each time accumulates. If you load it into FSx for Lustre once, all tuning jobs share high-speed access and total time and cost drop significantly. EFS has lower throughput than Lustre, but its setup is simple and it is good for persistent sharing. The key decision criterion: repeated, high-throughput = Lustre; shared, general-purpose = EFS; one-off large streaming = S3 Pipe.
Data Formats: RecordIO and Parquet
Using raw CSV, JSON, and images directly for training makes I/O slow because of parsing overhead and the small-file problem. ML prefers two formats.
Format Selection Table
| Format | Structure | Strength | When to use |
|---|---|---|---|
| CSV | Row-based text | Human-readable, supported everywhere | Small scale, quick checks |
| JSON / JSON Lines | Row-based semi-structured | Flexible schema | Raw logs, labeling manifests |
| Parquet | Columnar binary | Column-selective reads, high compression | Structured feature analytics and ETL, Athena · Glue · Spark |
| RecordIO-protobuf | Record-bundled binary | Optimal for sequential reads and Pipe streaming | Large-scale training with SageMaker built-in algorithms |
| TFRecord / tar shards | Record bundles | Consolidating small files | Millions of images and audio files |
RecordIO-protobuf is the recommended format for SageMaker built-in algorithms. It bundles many records into one large binary, which is optimal for sequential reads and Pipe mode streaming.
import io, numpy as np
import sagemaker.amazon.common as smac

# Serialize a numpy matrix to RecordIO-protobuf and upload to S3
buf = io.BytesIO()
smac.write_numpy_to_dense_tensor(buf, X_train.astype("float32"), y_train.astype("float32"))
buf.seek(0)

import boto3
boto3.client("s3").upload_fileobj(buf, "my-lake", "features/train/data.recordio")
Parquet is a columnar storage format. Because it stores data by column rather than by row, ① it reads only the columns needed (projection pushdown), ② it has a high compression ratio per column, and ③ Athena, Glue, and Spark read it natively. It is the de facto standard for structured feature data.
import pandas as pd
# Compared to CSV, Parquet gives column-selective reads + high compression → less ETL and analytics I/O
df.to_parquet("s3://my-lake/features/train.parquet", engine="pyarrow", compression="snappy")
# If only some columns are needed for training, scan only those → I/O drops sharply
cols = pd.read_parquet("s3://my-lake/features/train.parquet", columns=["age", "amount", "label"])
[Row-based CSV] row1: a,b,c,d,e | row2: a,b,c,d,e | ... → scans everything even if only 3 columns are needed
[Columnar Parquet] all of column a | all of column b | all of column c | ... → reads only the needed column blocks
A row-based format (CSV) must read a whole row, so it scans everything even if only 3 of 50 columns are needed. A columnar format (Parquet) stores each column separately, so it reads only the 3 needed. Moreover, values in the same column have similar types and distributions, so they compress well. That is why Parquet is the answer for structured data analytics and ETL, and RecordIO-protobuf is the answer for large sequential training with SageMaker built-in algorithms.
The Small-File Problem and Consolidation
If you leave millions of small images or JSON files in S3 as they are, per-object request overhead slows training.
- The solution is sharding — merge small files into large bundles such as RecordIO, TFRecord, or tar.
- If you make each bundle several hundred MB, sequential I/O is efficient and it also fits well with Pipe mode.
- As a side effect,
ShardedByS3Keyworks properly. Sharding is per S3 object, so a single giant file is not split across instances.
⚠️ Pitfall: It is not enough to say "the data is big, so I turned on ShardedByS3Key." The data must be split into multiple S3 objects for the distribution to take effect. Applying sharding to a single 100 GB file does nothing.
Partitioning and S3 Cost Management
A data lake is not "a place to just throw things into S3." How you lay it out determines every scan cost afterward.
- Partitioning: Split directories by the keys you filter on often, like
s3://bucket/dt=2026-06-26/region=kr/. Athena and Spark skip unneeded partitions entirely (partition pruning). - Beware of too many partitions: If you split partitions too finely (for example, by the second), small files explode and things get slower instead.
- Storage classes: Keep frequently read training data in S3 Standard, and move historical raw data kept for retraining down to Intelligent-Tiering or the Glacier family to cut storage cost.
- Version pinning: If you record the data snapshot path used for training in the job configuration, you can reproduce "that model from back then."
If you put training data in a Glacier-family class, storage is cheap, but restore latency means a training job cannot read it right away. If there is an "immediately usable for training" requirement, archive storage is the wrong answer.
Storage Selection Decision Tree
Is the data read repeatedly many times?
├─ Yes → Do multiple nodes read it simultaneously at high throughput?
│        ├─ Yes → FSx for Lustre (S3-integrated cache)
│        └─ No → EFS (shared, general-purpose, simple setup)
└─ No → Is the data large?
             ├─ Yes → If access is sequential, S3 + Pipe
             │        If random access is needed, S3 + FastFile
             └─ No → S3 + File (simplest)
The Order of Thinking for Storage Design
- How large is the data → at hundreds of GB or more, with File mode you must accept the startup delay.
- Is access sequential or random → sequential means Pipe; if random is needed, FastFile or a file system.
- How many times is the same data read → if repeats are many, FSx for Lustre pays for itself.
- Who shares it → if multiple notebooks and jobs read and write at the same time, EFS.
- What format is it → structured analytics uses Parquet, large training with built-in algorithms uses RecordIO-protobuf, and small files are sharded.
Tomorrow we cover where this data comes from in the first place (Kinesis and Glue, batch vs streaming).
📖 Glossary
- Input mode : The way to bring training data from S3 into the container. Three kinds: File, Pipe, and FastFile.
- time-to-first-batch : The time from the training job starting to actually processing the first batch. The key to GPU idle cost.
- ShardedByS3Key : A distribution setting that splits S3 objects by the number of instances so each reads only a different piece.
- FullyReplicated : The default distribution setting where every instance receives the whole data identically.
- EFS : A managed NFS file system that multiple instances mount at the same time. Simple to set up and elastically scalable.
- FSx for Lustre : A parallel file system for HPC. With S3 as the backend, it acts like a high-speed cache.
- RecordIO-protobuf : A format that bundles many records into one large binary. Optimal for sequential reads and Pipe streaming.
- Parquet : A binary format that stores data by column. It reads only the needed columns and has a high compression ratio.
- Sharding : The work of splitting or merging data into appropriately sized bundles to suit distributed processing.
- Partitioning : Dividing S3 paths by the keys you filter on often. It lets you skip unneeded ranges entirely.
📝 Practice Questions
Click a choice to reveal the answer and explanation.
Question 1
You are training 800GB of data across 4 ml.p3 instances in a distributed setup. To minimize the time GPUs sit idle waiting for data copies while having each instance read only a different slice of the data, what should you use?
Question 2
You run 200 rounds of hyperparameter tuning on the same ImageNet dataset, and the repeated S3 download time is accumulating into significant cost. What is the most appropriate storage strategy?
Question 3
In a structured feature table with 50 columns, analytics and ETL read only 3-5 columns each time. Which format reduces both I/O and storage cost at once?
Question 4
What is the recommended serialization format when training a SageMaker built-in algorithm on large data with Pipe-mode sequential streaming?
Question 5
Multiple data scientists' notebooks and multiple processing jobs need to simultaneously share and modify the same medium-sized dataset as a POSIX file system. Which choice is simple to set up and scales elastically?