Based on the MLA-C01 exam guideReport an error
MLA-C01· AssociateWeek 3 · Day 3~26 min read
Day 3 - SageMaker Feature Store: Managing Features as Assets
📌 Key Takeaways
- Feature Store is a repository that centrally stores, reuses, and consistently serves features. Its unit is the Feature Group.
- The required elements of a Feature Group are the Record Identifier (row identifier) and the Event Time (time of recording).
- The online store = millisecond single-record lookups (real-time inference), the offline store = S3 Parquet history (training and batch).
- Its greatest value is preventing training/serving skew — training and inference share the same feature definition.
- A point-in-time correct join based on Event Time prevents future information leakage (look-ahead bias).
What Is Feature Store
If the features you built yesterday exist only in a dataframe in a notebook, the next project has to build the same features again. Worse, the transformation used at training time and the one used at inference time can differ subtly, so model performance quietly collapses.
Feature Store is a repository that centrally stores, manages, and serves ML features. Its core unit is the Feature Group, which is made of rows and columns like a relational table, with each column being one feature.
| Required element | What it is | Why it is needed |
|---|---|---|
| Record Identifier | The key that identifies each row (for example, customer_id) | The key for online lookups, and the basis for deciding the latest value |
| Event Time | The time at which that feature value was recorded | The basis for point-in-time consistency (time travel) |
from sagemaker.feature_store.feature_group import FeatureGroup

feature_group = FeatureGroup(name='customer-features', ...)

feature_group.create(
    record_identifier_name='customer_id',   # Row identifier
    event_time_feature_name='event_time',    # Event time
    role_arn=role,
    enable_online_store=True                 # Enable the online store
)

# Ingest features
feature_group.ingest(data_frame=df, max_workers=3)
When multiple records with different event_time values accumulate for the same customer_id, you can reconstruct "what was the feature value at a particular point in time."
History of customer_id = cust_123

event_time          purchase_30d   activity_score
2026-01-15 10:00        12             0.71
2026-03-02 09:30        18             0.83
2026-06-24 14:10        25             0.66   ← the "latest value" the online store returns

The offline store keeps all three rows above → past points in time can be reconstructed
Event Time is related to the bitemporal concept in time series databases. When training a model on past data, you must use only "the feature values that could actually be known at that time" to prevent future information leakage (look-ahead bias). For example, if you predict a January 2024 transaction using a feature value that was updated in March 2024, you have seen the future. Event Time-based lookup is the mechanism that guarantees this temporal consistency.
Online Store and Offline Store
The core of Feature Store is that it provides two kinds of stores at the same time. On the exam you need to distinguish the two.
| Category | Online store | Offline store |
|---|---|---|
| Purpose | Real-time inference | Training and batch |
| Latency | Milliseconds (low latency) | High (batch) |
| Storage method | Fast key-value lookup | S3 (Parquet) |
| Lookup unit | 1 latest record (GetRecord) | Full history (bulk) |
| Cost | Relatively high | Cheap (S3) |
| API used | GetRecord (single record) | Athena query / direct S3 |
| Answer keywords | "milliseconds", "real-time inference", "single record" | "training dataset", "full history", "bulk lookup" |
# Online store: look up the latest features during real-time inference
record = featurestore_runtime.get_record(
    FeatureGroupName='customer-features',
    RecordIdentifierValueAsString='cust_12345'
)

# Offline store: build a training dataset (Athena)
query = feature_group.athena_query()
query.run(query_string="SELECT * FROM customer_features WHERE ...",
          output_location='s3://my-bucket/query-results/')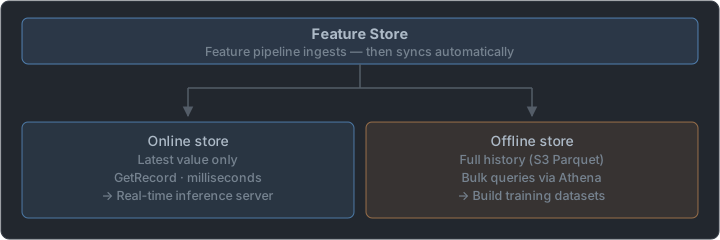
⚠️ Trap: If you enable only the online store, training history is not accumulated in S3, and if you enable only the offline store, you cannot do low-latency lookups in real-time inference. Most real ML systems enable both, so the same features are used consistently for training (offline) and inference (online). When you ingest data, SageMaker automatically syncs the latest value to the online store and the history to the offline store.
Consistency: Preventing training/serving Skew
The greatest value of Feature Store is that training and inference share the same feature definition. Training/serving skew is the classic problem in which the way features are computed differs between training and serving, degrading model performance.
A typical scenario: the training pipeline computes "average purchase amount over the last 30 days" with pandas, and the inference server recomputes the same value in Java. If the two implementations differ subtly (boundary handling, rounding), the values the model sees differ from those at training time.
| Cause of skew | Concrete example | Feature Store's solution |
|---|---|---|
| Duplicate implementation in two languages | Python for training / Java for serving | Compute once, both sides only read |
| Different interpretation of boundary conditions | Whether "last 30 days" includes today | The definition is fixed in the store |
| A bug fix reflected on only one side | Only the training code was fixed | A single definition, so it is reflected simultaneously |
| Time mismatch | A newer value was used at inference | Time consistency through Event Time |
[Feature computation pipeline]  ──ingest──>  [Feature Store]
                                                |
                          ┌─────────────────────┴──────────────────┐
                          v                                          v
                [Offline store]                              [Online store]
                Build training datasets                  Real-time inference lookups
                (Athena, same definition)                (GetRecord, same definition)
Training/serving skew is a core problem emphasized in Google's paper "Hidden Technical Debt in Machine Learning Systems," which dealt with the technical debt of ML systems. Model code is a small part of the whole ML system, and data pipelines and feature consistency are the main causes of failure. Feature Store reduces this debt by promoting features from "code" to a "shared data asset," gathering the definition in one place.
Feature Reuse and Governance
The second value of Feature Store is reuse. Features such as "customer lifetime value" and "recent activity score" built by Team A can be taken as they are by Team B for a new model.
| Capability | What it solves |
|---|---|
| Search and discovery | The problem of not knowing which features already exist and building duplicates |
| Metadata and descriptions | The problem of not knowing exactly what a feature means |
| Version and lineage | The problem of being unable to trace when and how it was created |
| IAM permissions | The problem of anyone accessing sensitive features |
Feature Store has a capability to join several Feature Groups with point-in-time consistency. When building training data, if you join customer features and product features on their respective event times, only "the values that could be known at that time" are combined exactly. This is called a point-in-time correct join, and it automates the prevention of future leakage, which is very tricky to do by hand.
Wrong join (future leakage)              Correct point-in-time join
Prediction time: 2026-01-15              Prediction time: 2026-01-15
customer feature: value of 2026-03-02 ✗  customer feature: latest value before 2026-01-15 ✓
  → Saw information from two months later    → Uses only values known at that time
A fintech company ran two models, fraud detection and credit scoring, and both needed a feature called "recent transaction frequency." At first each team computed it separately, so the definitions differed subtly, and when one team fixed a bug it was not reflected in the other. After this feature was defined once and shared through Feature Store, the definition mismatch disappeared, and fixing one place improved both models together.
Data Flow Summary
A typical pipeline connects like this.
| Order | Stage | Tool |
|---|---|---|
| ① | Transform raw data into features | Data Wrangler / Processing Job |
| ② | Load into Feature Store (online + offline at the same time) | ingest |
| ③ | Build the training dataset | Offline store + Athena |
| ④ | Look up the latest features in real time | Online store + GetRecord |
This whole flow shares the same feature definition, so consistency is maintained.
Exam discrimination summary
| Scenario wording | Answer |
|---|---|
| "Look up the user's latest features within milliseconds" | Online store GetRecord |
| "Query the full history for training in bulk" | Offline store + Athena |
| "Performance degrades because training and inference computations differ" | Unify the definition with Feature Store |
| "Must use only the values known at that time" | Event Time-based point-in-time join |
| "Two teams build the same feature separately" | Share and reuse a Feature Group |
Store Enablement Combinations and Results
When you create a Feature Group, which of online and offline you turn on determines what you can do afterward.
| Combination | What is possible | What is impossible | Suitable for |
|---|---|---|---|
| Online only | Millisecond single-record lookups | Training history lookups | Serving-only, where training data already exists separately |
| Offline only | Bulk history lookups, training set creation | Low-latency real-time lookups | Pipelines that only do batch inference |
| Both | Both training and inference | — | Most real ML systems |
- With both turned on, a single
ingestreflects the latest value in the online store and the history in the offline store. - If you later need training history but had the offline store turned off, the history for that period cannot be recovered.
Which Features to Put in Feature Store
Putting in every column is not the answer. There is a balance between management cost and value.
| Features worth putting in | Reason |
|---|---|
| Aggregate features that are expensive to compute | Recomputing every time is costly |
| Features commonly used by several models | The reuse effect is large |
| Features needed in both training and inference | The skew prevention effect is direct |
| Features whose definition is subtle and leads to misunderstanding | Pinned down with a single definition |
| Things you need not put in | Reason |
|---|---|
| Original raw columns as they are | Already in the data lake |
| Features used one-off in a single model | Low reuse value |
| Values computed on the fly at every request | No storage benefit |
The Moment Point-in-Time Consistency Breaks
Time to predict: 2026-01-15
   │
   ├─ Correct: use the latest record among those with event_time <= 2026-01-15
   │
   └─ Wrong: use the latest record (2026-06-24) as it is
                → Effectively feeds information from 5 months later into training
| Situation | Why it is dangerous |
|---|---|
| Joining the "current latest value" while building a past training set | Future information explains the label |
| Joining several Feature Groups on different criteria | Only some features see the future |
| Recording Event Time mistakenly as the ingestion time | Misaligned with the actual observation time |
⚠️ Trap: When backtest performance is unusually good, doubt point-in-time consistency first, before celebrating the performance. A training set that did not use a point-in-time correct join almost always produces optimistic numbers.
In the next lesson we look at data bias and quality, and SageMaker Clarify, which check whether the data prepared this way is fair and balanced.
📖 Glossary
- Feature Store : A repository that gathers ML features centrally and serves them consistently to training and inference.
- Feature Group : The basic unit of Feature Store. A table of rows and columns where the features become the columns.
- Record Identifier : The key that distinguishes each row. For online lookups, the latest record is found with this value.
- Event Time : The time at which that feature value was recorded. The basis for reconstructing past points in time and preventing leakage.
- Online store : A key-value store that returns 1 latest feature record within milliseconds. For real-time inference.
- Offline store : A store that accumulates all history in S3 as Parquet. For building training datasets.
- GetRecord : The API that fetches one latest record by identifier from the online store.
- training/serving skew : The phenomenon where feature computation differs between training and inference, so the model quietly gets worse.
- point-in-time correct join : A join method that combines only "the values that could be known at that time" relative to the prediction time.
- look-ahead bias (future leakage) : An error in which information after the prediction time is used in training, inflating performance.
📝 Practice Questions
Click a choice to reveal the answer and explanation.
Question 1
A real-time recommendation service must query latest features for a user in milliseconds every time they open a page. What's suitable in SageMaker Feature Store?
Question 2
Training pipeline in Python and inference server in Java each calculated "average purchase amount last 30 days" with subtle differences degrading model performance. How to fundamentally solve?
Question 3
What must be specified when creating Feature Group and serves as the basis for reconstructing feature values at specific points in time?
Question 4
To build a training dataset, query entire feature history in Feature Store in bulk. Most suitable method?
Question 5
Two teams each created identical "customer activity score" feature with mismatched definitions and bug fixes reflecting only partially. Feature Store solution?