Based on the DVA-C02 exam guideReport an error
DVA-C02· AssociateWeek 1 · Day 1~35 min read
Day 1 - AWS from a Developer's Perspective: Regions, Infrastructure, and the Boundary of Responsibility
When you join a new company and first get the AWS console, you usually run into two things first. One is "which Region should I create this in?" and the other is "do we have to manage this, or does AWS take care of it?" If SAA answers these questions with "how do I design this as an architect," DVA has to answer with "how do I put code and builds on top of it as a developer." It is the same infrastructure map, but from a different point of view.
In this post we dig into AWS's global infrastructure only as far as a developer needs to know, but down to the point where SDK calls and endpoint selection get deep. The goal is not to memorize exam keywords, but to understand why region_name is needed when you create a boto3 client, how IAM roles come into play in code behavior, and in which AZ a Lambda function runs.
The Shift in Development Paradigm Created by Cloud Computing
On March 14, 2006, S3 launched generally and the cloud computing era began. Until then, for a developer to release a new feature they had to go through four steps: ① a server quote, ② a data center colocation contract, ③ OS and middleware installation, ④ deployment, and even a short one took weeks. S3, and EC2, which came out the next year (August 2006), cut this cycle down to minutes. The real change AWS made was not "renting out servers" but the model of "Infrastructure as API." Once infrastructure became a resource you can call from code, the whole set of modern DevOps practices such as CI/CD, IaC, and Auto Scaling became possible.
Academically, NIST SP 800-145 (2011) summarizes this as the five essential characteristics of cloud: ① on-demand self-service, ② broad network access, ③ resource pooling, ④ rapid elasticity, ⑤ measured service. When you see keywords like "cost model, scalability, agility" on the DVA exam, you just need to identify which of these five aspects is being asked about.
Seen through distributed systems theory, "Infrastructure as API" leads naturally to declarative configuration (Kubernetes, Terraform, CloudFormation). Instead of imperatively saying "create N servers," you declaratively write "the desired end state is N servers," and the system runs a reconciliation loop to converge on that state. CloudFormation, SAM, and CDK, which you meet in DVA, are all different implementations of the same philosophy.
You also need to memorize the three deployment models (Public / Private / Hybrid), but on the real exam they appear as scenarios. "Leave the on-premises SAP as is and move only the new microservices to the cloud" is Hybrid. "Because of electronic financial supervisory regulations some data cannot leave" is answered by Outposts or Hybrid.
Regions, AZs, Edge: How Developers Choose an Endpoint
AWS's global infrastructure is a three-tier structure of Region > AZ > Edge Location. This structure matters to developers because it determines where a single line of SDK call goes.
import boto3

# Explicitly specify the Region — this determines the endpoint
s3 = boto3.client('s3', region_name='ap-northeast-2')

# Uses the AWS_REGION environment variable or the default region in ~/.aws/config
ddb = boto3.client('dynamodb')
When you write region_name='ap-northeast-2' here, the SDK sends an HTTPS request to the endpoint s3.ap-northeast-2.amazonaws.com. If you specify the wrong Region, you either create data in a different Region (cost and legal issues) or cannot find the resource at all (a NoSuchBucket error). So when a scenario on DVA asks "why is our code getting a 404," you should suspect region_name or endpoint_url first.
| Infrastructure tier | Count (2026) | Meaning from a developer's view |
|---|---|---|
| Region | 34 | The deciding unit for data location, pricing, and endpoint URL |
| Availability Zone | 3 or more per Region | Where EC2/Lambda actually run, the failover unit for Multi-AZ DBs |
| Edge Location | 600+ | CloudFront cache, the execution point for Lambda@Edge |
| Local Zones | 30+ | 1-2ms ultra-low latency. Media, gaming, real-time ML inference |
| Wavelength | Carrier 5G edge | Autonomous driving, industrial IoT |
| Outposts | AWS racks in the customer DC | Satisfies data sovereignty + the AWS API at the same time |
AWS service endpoints fall into three broad kinds. A Regional endpoint (e.g., dynamodb.ap-northeast-2.amazonaws.com) is the most common form and routes to different infrastructure per Region. A Global endpoint (e.g., iam.amazonaws.com, s3.amazonaws.com) reaches a global service without a Region. A FIPS endpoint (e.g., dynamodb-fips.us-east-1.amazonaws.com) is an endpoint that uses FIPS 140-2 validated cryptographic modules, meant for US government and financial customers. You can switch to it automatically with the SDK environment variable AWS_USE_FIPS_ENDPOINT=true.
After the April 2011 us-east-1 EBS outage, AWS established a principle of building every new Region with at least 3 AZs. Before that, an AZ was little more than a different rack within the same facility, but this event enforced the definition of "a set of one or more DCs with physically independent power, cooling, and networking." Latency between AZs is usually within 1-2ms, so synchronous replication like RDS Multi-AZ is possible, but they are placed at a distance (a few km to tens of km) such that a fire or power outage will not spread.
The February 28, 2017 S3 us-east-1 outage. An operator made a typo in a billing debugging command, stopped more servers than intended, and the index subsystem went into a full restart. Stripe, Slack, Trello, IFTTT, Coursera, and Quora were down for 4 hours, and the AWS Status Page itself depended on S3, creating the situation of "there's an outage but the status board is green." AWS later split the Status Page across multiple Regions. AWS official post-mortem. The lesson for developers is clear: a system that depends on a single Region dies with that Region whenever any of its services dies.
Where Is an AZ Really: The Difference Between ZoneName and ZoneId
This shows up often on the exam and has many traps in practice. When one company has two AWS accounts, ap-northeast-2a in account A and ap-northeast-2a in account B are physically different AZs. This is because AWS deliberately shuffles the mapping per account to prevent the load concentration of "everybody creates in a first."
aws ec2 describe-availability-zones \
  --region ap-northeast-2 \
  --query 'AvailabilityZones[*].[ZoneName,ZoneId]' \
  --output table

# Output:
# ap-northeast-2a   apne2-az1
# ap-northeast-2b   apne2-az2
# ap-northeast-2c   apne2-az3
# ap-northeast-2d   apne2-az4
ZoneId (apne2-az1) points to the same physical AZ in every account. If you want to save cross-AZ data transfer costs when connecting with a partner through VPC peering or PrivateLink, you must match by ZoneId. If you pair a-with-a by ZoneName alone, it is often actually cross-AZ.
⚠️ Trap: It is easy to assume that because you created a subnet in
ap-northeast-2awhen creating the VPC, placing the partner's PrivateLink in the same a automatically attaches it to the same physical AZ. That is wrong. A PrivateLink endpoint network interface is assigned an AZ per ENI, and if the AZ mappings of the two accounts differ, traffic flows cross-AZ and an additional $0.01 per GB cost is incurred. A similar cost arises when the client is in a different AZ even after an RDS Multi-AZ failover.
An Edge Location Is Not Just a Cache
Edge locations do 4 different jobs across more than 600 PoPs (Points of Presence): CloudFront (HTTP/HTTPS caching and TLS termination), Route 53 (authoritative DNS responses), Global Accelerator (TCP/UDP Anycast acceleration), and AWS WAF/Shield (edge DDoS filtering). The key thing developers need to know is the difference between CloudFront and Global Accelerator.
| Dimension | CloudFront | Global Accelerator |
|---|---|---|
| OSI layer | L7 (HTTP/HTTPS) | L4 (TCP/UDP) |
| Cache | Yes | No |
| Anycast IP | No (DNS-based) | Yes (2 static IPs) |
| Suitable workloads | Static and dynamic web content | Gaming, MQTT, VoIP, WebRTC |
| Failover time | Minutes (DNS TTL) | Seconds (BGP rerouting) |
The 2 static IPs that Global Accelerator provides are based on BGP Anycast. When the same IP is advertised by BGP from multiple edges, the client's ISP routes to the nearest edge according to the BGP best-path algorithm (RFC 4271), such as AS_PATH length and local preference. With DNS, changes propagate over minutes because of the TTL cache in the client resolver, but BGP propagates within seconds through KEEPALIVE/UPDATE between routers. This is the mechanism by which Global Accelerator guarantees "second-level failover."
CloudFront Functions and Lambda@Edge are also frequently confused. CloudFront Functions run directly at 600+ edges with a cold start under 100μs, but have limits of 2MB memory and 1ms execution time. They support only JavaScript ES5.1 and cannot make external API calls. Simple viewer request header modification and A/B test routing are about the limit. Lambda@Edge runs at 13 Regional Edge Caches and can use the full Node.js and Python runtimes, but cold starts are in the tens of ms. If you need DynamoDB lookups or external API calls, you must go with Lambda@Edge.
The Shared Responsibility Model: How Far Is a Developer Responsible for Their Own Code
A common misunderstanding among developers new to the cloud is "AWS will handle security too." In reality there is a clear division: AWS = Security OF the Cloud / Customer = Security IN the Cloud. More important is that the responsibility boundary moves up and down depending on the abstraction level of the service you choose.
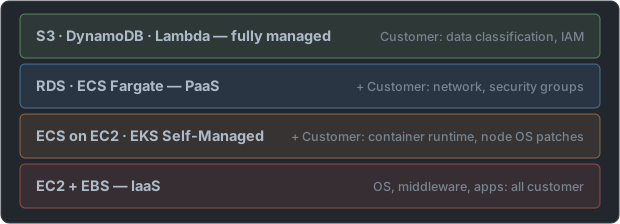
Even for the same "DB query," with RDS the engine patching, backups, and OS are AWS's, while writing queries, index design, and SG configuration are the customer's. If you install MySQL directly on EC2, even OS patching comes down to the customer. With Lambda, even runtime security patches are AWS's responsibility, and the customer only needs to care about code vulnerabilities and IAM permissions. If you memorize the principle that the higher the abstraction level, the higher the responsibility boundary moves, questions about who is responsible become easy to solve.
The July 2019 Capital One data breach. The perpetrator was a former AWS employee, Paige Thompson, but the cause was not AWS infrastructure; it was an SSRF vulnerability in the WAF that Capital One operated + the exposure of an IAM role through EC2 IMDSv1. The attacker used SSRF to access http://169.254.169.254/latest/meta-data/iam/security-credentials/, stole temporary credentials, and used those credentials to read the card application data of 106 million people from S3 buckets. As a direct result, AWS released IMDSv2 (session-token based) in November 2019. DOJ indictment.
🔍 Going deeper: IMDSv2 works in two steps. ① A
PUT /latest/api/tokenrequest receives a session token via theX-aws-ec2-metadata-token-ttl-secondsheader. ② When making a metadata request, present the token with theX-aws-ec2-metadata-tokenheader. An SSRF attacker can usually only send HTTP GET, so they cannot send the PUT and cannot get the token. IMDSv2 also forces the IP TTL to 1 (a hop limit of 1), so it cannot escape outside the container network. When creating an EC2 instance, settingMetadataOptions.HttpTokens=requiredforcibly disables IMDSv1.
The 4 Domains the DVA Exam Asks About
Unlike SAA, DVA puts the weight on security, deployment, and troubleshooting from the developer's perspective.
| Domain | Weight | Key keywords |
|---|---|---|
| Development | 32% | Lambda, API Gateway, DynamoDB, SDK, SAM |
| Security | 26% | IAM, KMS, Cognito, Secrets Manager |
| Deployment | 24% | CodePipeline, CodeBuild, CodeDeploy, Beanstalk, CloudFormation |
| Troubleshooting | 18% | CloudWatch, X-Ray, CloudTrail |
If SAA asks "how will you design it," DVA asks "how will you build it in code, deploy it, and debug it." For example, for the scenario "Lambda is slow because of cold starts," SAA is satisfied with "set up a warm pool," but DVA must be answered down to code and option names: "attach Provisioned Concurrency to the alias, and on changes switch with CodeDeploy Canary 10Percent5Minutes."
Trying It Out Directly with the CLI
# 1) All currently available Regions
aws ec2 describe-regions --output table

# 2) AZs in the Seoul Region — look at ZoneName and ZoneId together
aws ec2 describe-availability-zones \
  --region ap-northeast-2 \
  --query 'AvailabilityZones[*].[ZoneName,ZoneId,State,ZoneType]' \
  --output table

# 3) Which account/user/role the current credentials map to
aws sts get-caller-identity
get-caller-identity is the starting point of debugging. When you wonder "why does it say I don't have permission?", it is the first thing to run. From the ARN you can see at a glance whether it is an IAM user, which role was assumed, and which account it is in.
Summary
Today we saw two pictures. First, AWS runs on a three-tier infrastructure of Region > AZ > Edge, and for developers this structure is directly tied to where the SDK sends requests. Second, on top of that, the responsibility for security and operations is AWS from the concrete floor up through the hypervisor, and the customer above that, and the boundary moves up and down depending on which service you choose.
In the next post, we look at IAM's four core entities, which decide "who gets to do what" on top of that: User, Group, Role, and Policy. Recalling that in the Capital One incident the excessive permissions of the IAM role credentials stolen through SSRF magnified the damage, the reason developers need a deep understanding of IAM becomes obvious.
📝 Practice Questions
Click a choice to reveal the answer and explanation.
Question 1
When a boto3 client is created with s3 = boto3.client('s3'), how is the Region determined?
Question 2
A company uses an IAM role through IMDSv1 on its EC2 instances. The security team has asked to enforce IMDSv2 to counter SSRF attacks. What is the most accurate action?
Question 3
How is the AZ in which a Lambda function runs determined?
Question 4
Between Global Accelerator and CloudFront, which fits the following scenario? "We must provide an MQTT-based IoT messaging service to users around the world."
Question 5
A developer created an S3 bucket in us-east-1, but SDK calls from ap-northeast-2 have latency over 200ms. What is the most appropriate improvement?
Question 6
Which of the following is NOT a "customer responsibility" area?
Question 7
You are going to connect PrivateLink with a partner through VPC peering. Both accounts placed subnets in ap-northeast-2a, but the traffic flows cross-AZ. What are the cause and the fix?