Based on the DEA-C01 exam guideReport an error
DEA-C01· AssociateWeek 1 · Day 3~40 min read
Day 3 - A Bird's-Eye View of AWS Data Services
📌 Key Takeaways
- AWS data services are laid out along the ingest → store → process → analyze flow, and governance (catalog, permissions, encryption) wraps the entire span.
- Scenario questions first ask "which stage of the flow is this?", then narrow the candidates for that stage by source type, freshness, and operational overhead.
- The source decides ingestion: events = Kinesis/MSK, database changes = DMS (CDC), files = DataSync, SaaS = AppFlow.
- S3 is the default for storage, and the Glue Data Catalog is the common metadata that Athena, Redshift Spectrum, and EMR all look at together.
- Permissions work at different layers: IAM handles resources (buckets, APIs), Lake Formation handles tables, columns, and rows, and KMS handles encryption keys.
The Data Flow Is the Service Map
AWS has dozens of data-related services. When you first open the console, a flood of similar-looking names such as Kinesis, Glue, EMR, Redshift, Athena, and Lake Formation leaves you at a loss. But if you line them up in the order the data flows, a map emerges. Data always follows the flow of ingest → store → process → analyze, and governance (security and catalog) wraps across all of it.
Today we draw a map of which services belong where across these five categories. We will cover the deep details of individual services in later weeks; today's goal is to place in your head "which stage of the pipeline is this service in?" A good share of exam questions ask "which service fits this scenario?", and the answer comes from this map.
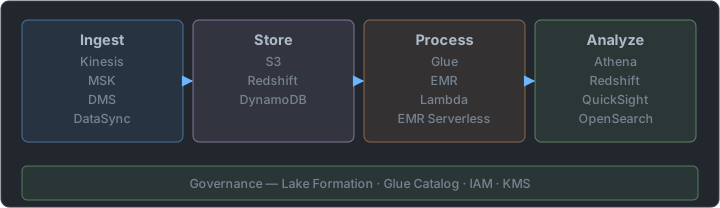
This single picture is the skeleton of DEA-C01 service knowledge. Data flows from the left (ingestion) to the right (analytics), and the governance layer at the bottom oversees permissions, catalog, and encryption across the whole span.
💡 Related theory: In industry-standard terms, this flow is called the "stages of a data pipeline." Each stage should be loosely coupled. For example, if you place S3 or a stream buffer between ingestion (Kinesis) and processing (Lambda), ingestion does not get blocked even when the processing stage is slow. This pattern of "separating stages with a buffer" is the heart of robust pipeline design.
Ingestion: Bringing Data In
This is the entrance for bringing data from a source into AWS. The tool differs depending on the nature of the source.
| Service | Purpose | When |
|---|---|---|
| Kinesis Data Streams | Real-time stream ingestion | Low latency, multiple consumers |
| Kinesis Data Firehose | Stream → S3/Redshift loading | Near-real-time automatic delivery |
| Amazon MSK | Managed Apache Kafka | Existing Kafka ecosystem |
| AWS DMS | DB migration/replication | RDS and on-premises DBs to S3/Redshift |
| AWS DataSync | Large-scale file transfer | On-premises NFS/SMB → S3 |
Key distinctions: real-time event streams go to Kinesis/MSK, to bring in the changes of an existing database use DMS (including CDC), and large chunks of on-premises files go to DataSync.
The real value of DMS is in CDC (Change Data Capture). It reads the transaction log of the production DB and continuously replicates "only the changes," so you keep the analytics environment current without dumping the whole thing each time. It is the standard way to flow data to OLAP while putting almost no load on OLTP.
Storage: Holding Data
This is where the ingested data stays. The OLTP/OLAP and lake/warehouse distinctions from Day 1 apply as they are.
| Service | Type | Role |
|---|---|---|
| Amazon S3 | Object storage | Foundation of the data lake, all raw data |
| Amazon Redshift | Data warehouse (OLAP) | Large-scale analysis of refined structured data |
| Amazon DynamoDB | NoSQL (OLTP) | Key-value, low-latency high-volume reads/writes |
| Amazon RDS/Aurora | Relational (OLTP) | Transactional operational DB |
S3 is at the center of everything. It is the foundation of the data lake and the input/output point of almost every processing and analytics service. When "where do I store it?" is vague, S3 is the default.
# S3 is the foundation of the data lake — store using a partition structure
aws s3 cp orders.parquet \
  s3://datalake/raw/orders/year=2026/month=06/day=25/

# Athena queries this S3 location directly with SQL (no separate loading needed)
# If the Glue Catalog knows the schema, you can query immediately
S3 storage classes (Standard, Intelligent-Tiering, Glacier, etc.) and lifecycle policies are the key to cost optimization. Automatically moving rarely used past data to cheaper tiers is the everyday work of a data engineer, and it is covered with real weight on the exam as well.
Processing: Transforming Data
These are the engines that cleanse and transform raw data into an analyzable form. You choose by data volume and the nature of the job.
| Service | Engine | Suitable work |
|---|---|---|
| AWS Glue | Serverless Spark | Managed ETL, catalog integration |
| Amazon EMR | Hadoop/Spark cluster | Large-scale, custom big data processing |
| AWS Lambda | Function | Lightweight event-driven transformation |
| Glue / EMR Serverless | Serverless | Spark without cluster management |
Glue is the "default for managed ETL." It runs Spark-based transformations without server management, and the Data Catalog, crawlers, and scheduler are integrated. EMR is used when you need more control and scale, or when you move existing Hadoop/Spark code over as is. Lambda suits small-unit, event-driven transformations (such as processing when a single file arrives).
A Glue Crawler scans S3 data, automatically infers the schema, and registers it as a table in the Glue Data Catalog. This catalog becomes the "common metadata dictionary" shared by Athena, Redshift Spectrum, and EMR. In other words, once registered in the catalog, multiple analytics engines see the same data with the same definition.
Analytics: Getting Answers from Data
This is the consumption layer that asks questions of the refined data.
| Service | Purpose |
|---|---|
| Amazon Athena | Serverless SQL queries over S3 |
| Amazon Redshift | Large-scale warehouse queries |
| Amazon QuickSight | BI dashboards and visualization |
| Amazon OpenSearch | Log and text search, real-time analytics |
Athena is a serverless tool that queries data loaded in S3 with SQL right where it sits, without moving it. There is no infrastructure and you are billed by the amount of data scanned, so it is ideal for occasional ad hoc analysis. If you query frequently, quickly, and at large scale, load the data into Redshift. To turn the final results into a dashboard that people look at, use QuickSight.
Governance: Controlling the Whole Span
This is the layer of security, catalog, and permissions that cuts across every stage from ingestion to analytics.
| Service | Role |
|---|---|
| AWS Lake Formation | Central permissions and governance for the data lake |
| AWS Glue Data Catalog | Unified metadata catalog |
| AWS IAM | Identity and access permissions |
| AWS KMS | Encryption key management |
Lake Formation grants fine-grained permissions at the "table, column, and row level" on the S3 data lake. Where IAM asks "can this person access this S3 bucket?", Lake Formation controls "can this person see up to this column of this table?"
The reason governance is a separate category is that in a data pipeline, security, permissions, and lineage are not a problem of one stage but a cross-cutting concern that runs through the entire span. The essence of governance is tracking who accessed which data, and where that data came from and where it went (data lineage).
Pieces Not Yet on the Map
The table above contains only the skeleton. The DEA-C01 scope includes more services that connect the stages or fill gaps. When you see a name, you should immediately recall "what goes in which box."
| Service | Position on the map | One-line role | Passage clue |
|---|---|---|---|
| Amazon AppFlow | Ingestion | Sets up data flows between SaaS such as Salesforce and AWS without code | "SaaS application data," "without code" |
| AWS Transfer Family | Ingestion | Receives files that outside parties upload via SFTP/FTPS into S3 or EFS | "Partner transfers via SFTP" |
| AWS Snow family | Ingestion | Loads onto a device and ships it physically | "The line is slow," "one-time large-volume transfer" |
| AWS SCT | Ingestion (paired with DMS) | Converts the schema and code of heterogeneous DBs | "Oracle → PostgreSQL/Redshift" |
| Amazon Managed Service for Apache Flink | Processing (stream) | Stateful real-time aggregation and joins | "Window aggregation," "real-time anomaly detection" |
| AWS Glue DataBrew | Processing (preparation) | Cleansing and profiling on a visual screen | "Analysts who don't write code," "data profile" |
| AWS Glue Data Quality | Processing/governance | Checks data quality with rules | "Completeness and uniqueness rules," "quality score" |
| Redshift Spectrum | Analytics | Queries S3 data from Redshift as external tables | "Query and join S3 with Redshift SQL without loading" |
| AWS Step Functions | Orchestration | Connects steps, retries, and branches with a serverless state machine | "Serverless workflow," "several AWS services in order" |
| Amazon MWAA | Orchestration | Managed Apache Airflow | "Existing Airflow DAG," "open-source compatible" |
| Amazon EventBridge | Orchestration/trigger | Starts execution with event rules and schedules | "When an event occurs," "cron schedule" |
| Amazon Macie | Governance | Finds sensitive information (PII) inside S3 | "Detect whether S3 has personal information" |
| AWS CloudTrail | Governance | Records who called which API | "Auditing," "who accessed it" |
- Orchestration is not the ingestion or processing stage itself but the layer that decides when and in what order those stages run. Glue workflows and triggers also belong here, but they are used only when tying together Glue jobs alone.
- The
Kinesis Data Firehosein the tables above is now named Amazon Data Firehose. Both spellings appear in exam passages.
Lookalike Service Decision Table
What tends to become a wrong answer in this track is the option where "both seem like they would work." Remember just one axis along which they split.
Ingestion: what is the source?
| Source | Service | Key point |
|---|---|---|
| Relational and NoSQL databases | DMS | Full load + continuous replication of changes via CDC. For heterogeneous DBs, convert the schema with SCT |
| NFS/SMB file servers, other object storage | DataSync | An agent transfers and verifies files. Scheduled incremental sync |
| Files pushed in by external partners | Transfer Family | AWS operates the SFTP/FTPS endpoint |
| SaaS applications | AppFlow | Choose a connector, then set up mapping and a schedule |
| Application events, logs, IoT | KDS, MSK, Firehose | Small records that keep coming without end |
- DMS moves rows and DataSync moves files. "Copy a database backup file to S3" is a file transfer, so it is DataSync; "keep a database's tables continuously synchronized" is DMS.
Processing: how big, and how much control is needed?
| Service | Conditions to choose it | Conditions not to choose it |
|---|---|---|
| Lambda | Lightweight transformation at the unit of one file or one event | Jobs where a single run exceeds 15 minutes (the function timeout ceiling), large-scale joins |
| Glue ETL | Serverless Spark, integrated with the catalog, crawlers, and bookmarks | When you need to fine-tune cluster settings, frameworks other than Spark |
| EMR | Multiple frameworks such as Spark, Hive, Presto, HBase; direct control of instances and settings; migrating existing Hadoop code | When "least operational overhead" is the condition (except EMR Serverless) |
| Athena (CTAS/INSERT INTO) | Transformations that finish with SQL alone, format conversion | Complex procedural logic, calling external systems |
Analytics: where does the data live and how often is it queried?
| Service | Data location | Billing structure | Fitting situation |
|---|---|---|---|
| Athena | S3 as is | Amount of data scanned by the query (there is also a way to buy capacity in advance) | Occasional ad hoc, log investigation |
| Redshift Spectrum | S3 as is (external tables) | Amount of data scanned + the Redshift cluster | Joining warehouse tables and S3 data in a single query |
| Redshift | Loaded into Redshift's internal storage | Node hours or serverless usage | Complex joins frequently and quickly, many concurrent users |
| OpenSearch | Indexed in an index | Domain instances and storage | Full-text search, log exploration, per-second dashboards |
Governance: what does it control?
| Service | Unit of control | Question |
|---|---|---|
| IAM | Resources and API calls | "Can this role use this bucket/job/query API?" |
| Lake Formation | Databases, tables, columns, rows, cells | "Can this analyst see the salary column of this table?" |
| KMS | Encryption keys | "Who can decrypt this data?" |
| Macie | S3 object contents | "Where is sensitive information contained?" |
| CloudTrail | API call history | "Who did what, and when?" |
⚠️ Pitfall: An option that tries to solve "column-level access control" with only an S3 bucket policy or an IAM policy is a wrong answer. S3 only knows down to the object level. What hides columns and rows inside an object is Lake Formation, which applies permissions to catalog tables.
What the Glue Data Catalog Actually Does
The catalog does not hold the data. It holds only the instruction manual: "where in S3 is this table's data, what are its columns and types, and in what format should it be read?"
-- Athena DDL: the data stays in S3 as is; only the manual is registered in the catalog
CREATE EXTERNAL TABLE orders (
  order_id   string,
  amount     double,
  region     string
)
PARTITIONED BY (dt string)
STORED AS PARQUET
LOCATION 's3://datalake/processed/orders/';

-- When a new date folder appears, you must tell the catalog about the partition for it to be queryable
ALTER TABLE orders ADD IF NOT EXISTS
  PARTITION (dt = '2026-06-25')
LOCATION 's3://datalake/processed/orders/dt=2026-06-25/';- The hierarchy is database → table → partition. A table points to the S3 path, format (SerDe), and columns, and a partition points to a sub-path.
- Even if you delete an external table with
DROP TABLE, the files in S3 remain. Conversely, even if you delete the S3 files, the catalog entry remains and you get empty results. - There are three ways to populate the catalog.
| Method | Behavior | Fitting situation |
|---|---|---|
| Glue crawler | Scans S3/JDBC, infers the schema, and registers tables and partitions | Raw data whose schema is unknown, paths where partitions grow periodically |
| Direct DDL/API registration | CREATE EXTERNAL TABLE, ALTER TABLE ADD PARTITION | A refined zone where the schema is already fixed, where the pipeline adds partitions itself |
| Partition projection (Athena) | Does not store the partition list in the catalog but computes it from rules in the table properties | When there are a great many regular partitions such as dates |
- A crawler costs money and time every time it runs. The cause of "a new file came in but I can't see it in Athena" is usually that the partition is not registered.
MSCK REPAIR TABLEonly adds new partitions, takes a long time, and cannot clean up deleted partitions. For partition management,ALTER TABLE ADD PARTITION, crawlers, and partition projection are better.
That several engines share one catalog is both a benefit and a responsibility. If someone changes a table's column type, not only Athena queries but also the Glue jobs, EMR jobs, and Redshift Spectrum external schemas that read that table are all affected at once. That is why Lake Formation manages not only the permission to query data but separately the permission to modify catalog metadata.
The Billing Method Tells You the Nature of the Service
The exam does not ask about amounts but about the structure. If you know "what the cost is proportional to," you can pick out the "most cost-effective" option.
| Service | What it is proportional to | So how to reduce it |
|---|---|---|
| S3 | Storage amount × storage class, number of requests | Transition classes with lifecycle rules, reduce small objects |
| Athena | Amount of data scanned | Columnar formats, compression, partition filters |
| Glue ETL | Processing capacity used by the job × run time | Read only the needed partitions, process incrementally with bookmarks |
| EMR | Time the cluster instances are on | Transient clusters that shut down when the work ends, Spot instances |
| Redshift | Time the nodes are on (provisioned) or capacity used (serverless) | Serverless if the usage pattern is intermittent |
| KDS | Number of shards × time (provisioned) or data written and read (on-demand) | Provisioned if traffic is steady |
| Data Firehose | Amount of data ingested | Direct PUT and KDS sources round record size up in 5 KB units for billing, so send very small records bundled together |
| Lambda | Number of invocations × run time × memory | Increase batch size |
- For occasional use, usage-based billing (Athena, Lambda, on-demand/serverless) is advantageous, and for continuous, fully loaded use, capacity-based billing (provisioned clusters and shards) is advantageous. This single line is the criterion for "serverless vs. provisioned" questions.
Scenario → Service Decision Table
| Scenario | Answer | Confusing wrong answer and why |
|---|---|---|
| Keep reflecting changes from an on-premises Oracle into Redshift | DMS (CDC) + SCT | DataSync — it is a file transfer tool, so it cannot follow table changes |
| Salesforce data to S3 every hour | AppFlow | Custom Glue job — possible, but it goes against "without code" |
| Investigate JSON logs in S3 with SQL a few times a month | Athena | Loading into Redshift — incurs always-on cluster cost |
| Complex joins for a dashboard that hundreds of people view daily | Redshift (+ QuickSight) | Athena — possible, but disadvantaged in concurrency and response consistency |
| A non-developer cleansing data by clicking | Glue DataBrew | Glue ETL — requires writing code |
| Move and operate an existing Airflow DAG as is | MWAA | Step Functions — requires rewriting the DAG |
| Check whether sensitive information such as national ID numbers is mixed into an S3 bucket | Macie | Lake Formation — it is permission control, not a detection tool |
| Different visible columns per analyst | Lake Formation | IAM/S3 bucket policy — controls only down to the object level |
In the next post, we look at what "form" the data flowing through this pipeline is stored in — CSV, JSON, Parquet, ORC, Avro, columnar vs. row-oriented, and schema evolution.
📖 Glossary
- Ingestion : The stage of bringing source system data into AWS. The tool differs depending on the type of source.
- CDC (Change Data Capture) : A method of reading a database's change log and continuously replicating only the changed rows.
- Data catalog : An instruction manual recording where data is and what its columns and formats are. It does not hold the data itself.
- Crawler : A Glue feature that scans a store, infers the schema and partitions, and registers them as tables in the catalog.
- External table : A table where the data stays in S3 and only the definition is registered. Deleting the table leaves the files.
- Partition : A unit that splits an S3 path by a value such as a date. It makes queries read only the folders that match the condition, reducing the scan amount.
- Serverless : A way of paying only for what you use without launching servers or clusters yourself. Athena, Glue, and Lambda qualify.
- Orchestration : Automatically chaining and running multiple jobs according to rules of order, conditions, and retries.
- Data lineage : The history of where data came from, what processing it went through, and where it went.
- Ad hoc query : A query thrown on the spot when needed, not decided in advance.
📝 Practice Questions
Click a choice to reveal the answer and explanation.
Question 1
Which option correctly orders the four-stage flow that forms the basic skeleton for understanding AWS data pipelines?
Question 2
You want to continuously replicate changes (CDC) from a live RDS database to the analytics environment (S3/Redshift) without operational load. Which ingestion service is the best fit?
Question 3
Which service lets you run ad-hoc SQL queries on data in S3 right where it sits — with no separate infrastructure and no data movement — billing only for the amount scanned?
Question 4
Which service centrally manages metadata so that multiple analytics engines (Athena, Redshift Spectrum, EMR) share the same data with identical schema definitions?
Question 5
If IAM controls "whether a bucket can be accessed," which governance service centrally grants fine-grained table, column, and row level access permissions on an S3 data lake?